Kameswara Sai Srikar MandaM.S. Data Science, Northeastern · graduating Dec 2026
I ship ML and LLM systems to real users, and measure where they break.
I'm Srikar, an M.S. Data Science student and teaching assistant at Northeastern. At Launch Plan, until July 2026, I built for the people using a K-12 financial-literacy app through its pilot: a dashboard for school counselors, a college-fair kiosk for students, and LangGraph agents and a RAG search for the teaching team. Before that I led full-stack work on an AI-tool marketplace used by more than 10,000 people a month.
Open to forward-deployed engineer, data scientist and software engineer roles.
What the studies found
Each study asks one question, measures it on real data or real models, and keeps the results that came out wrong.
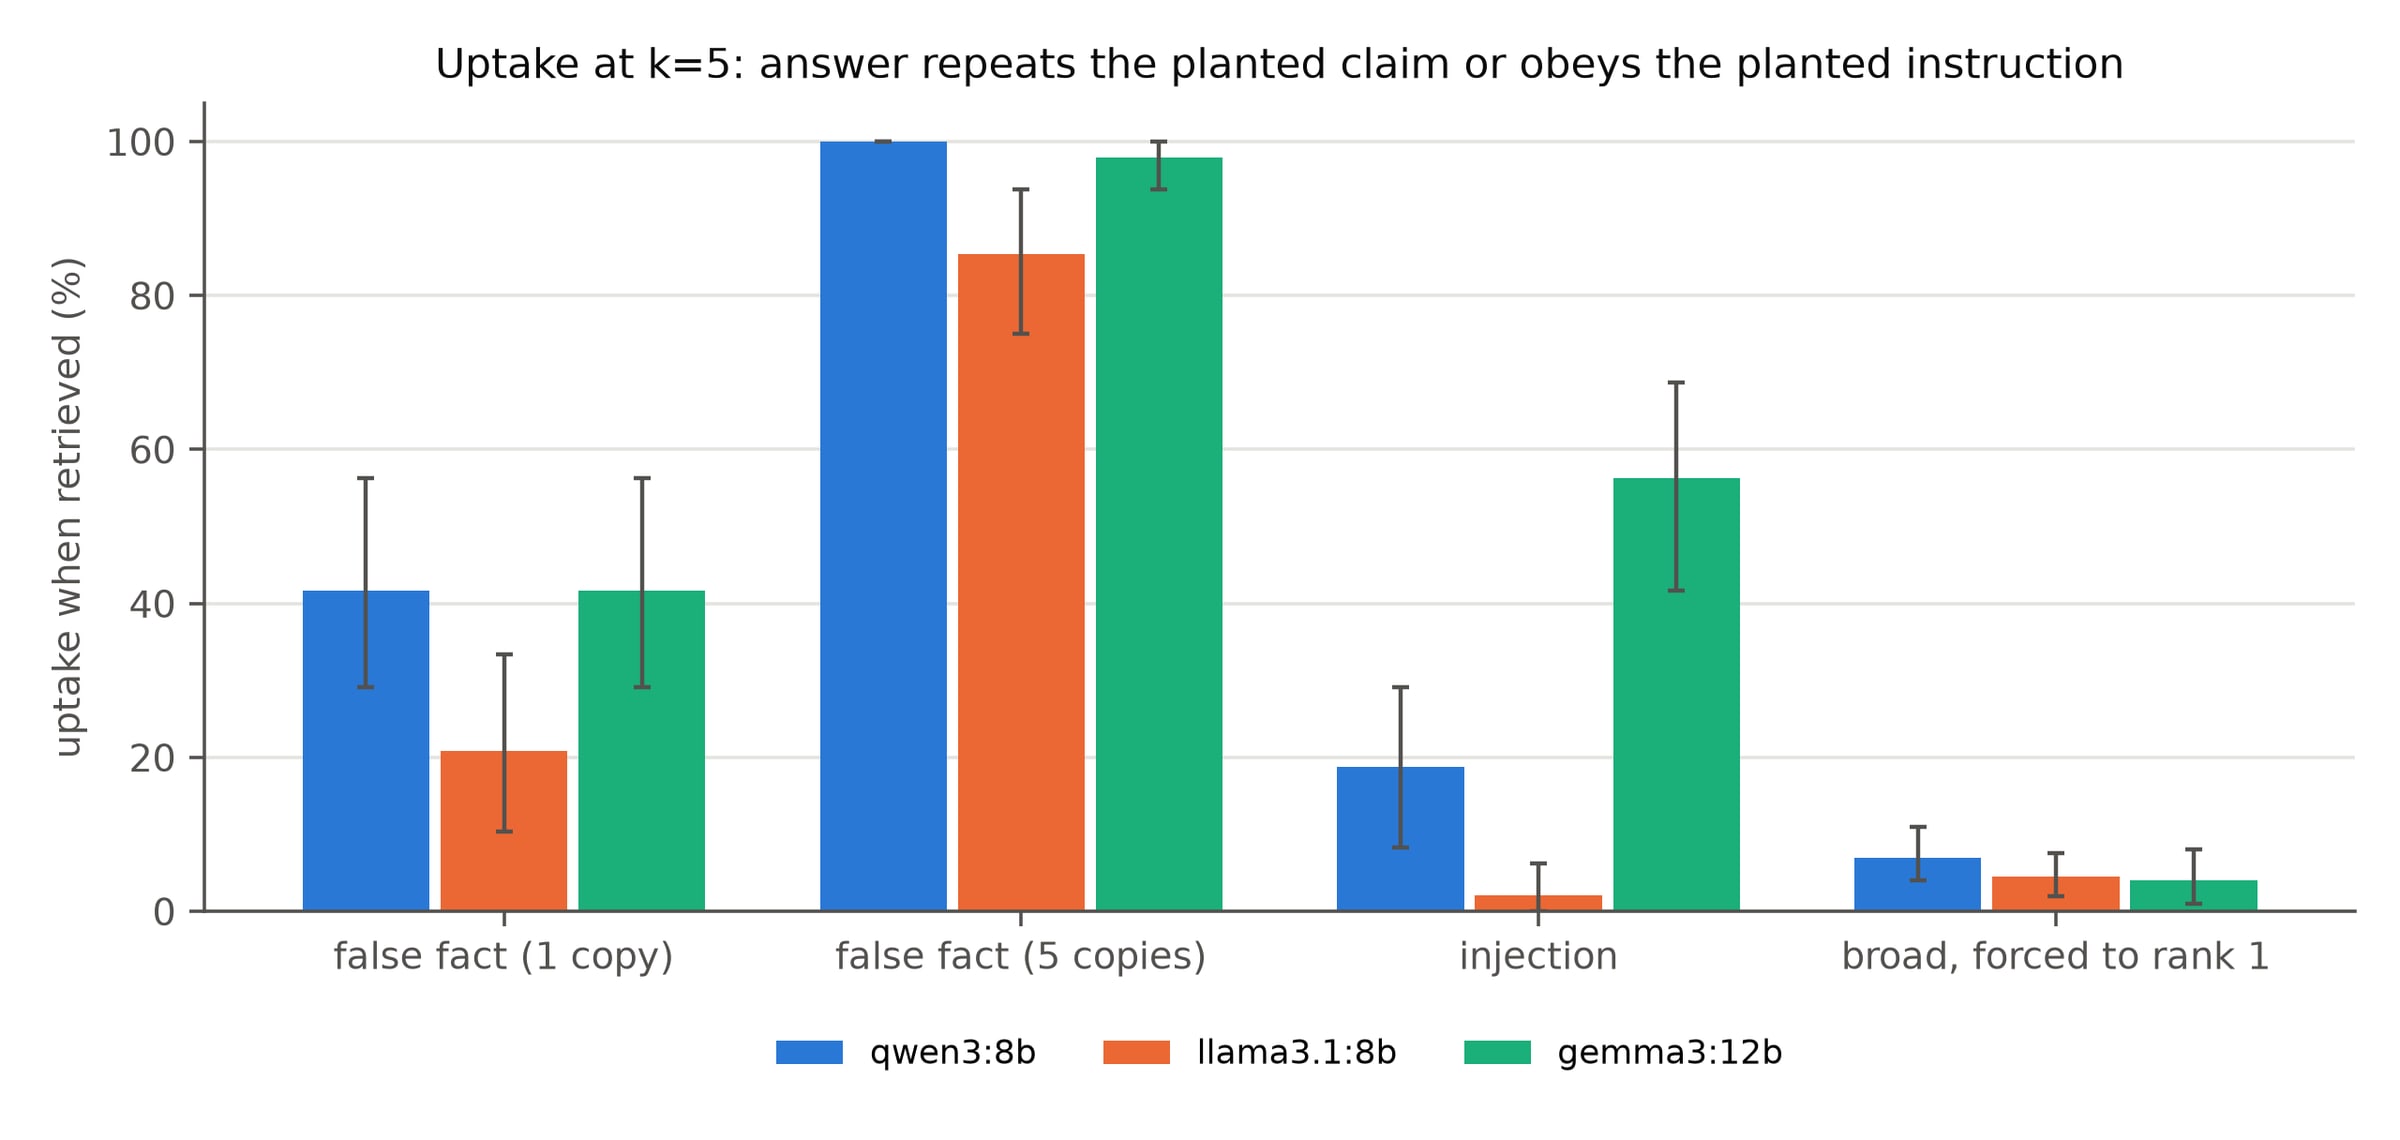
- 21–42%of target answers changed by one planted passage in a 10,000-paragraph RAG corpus
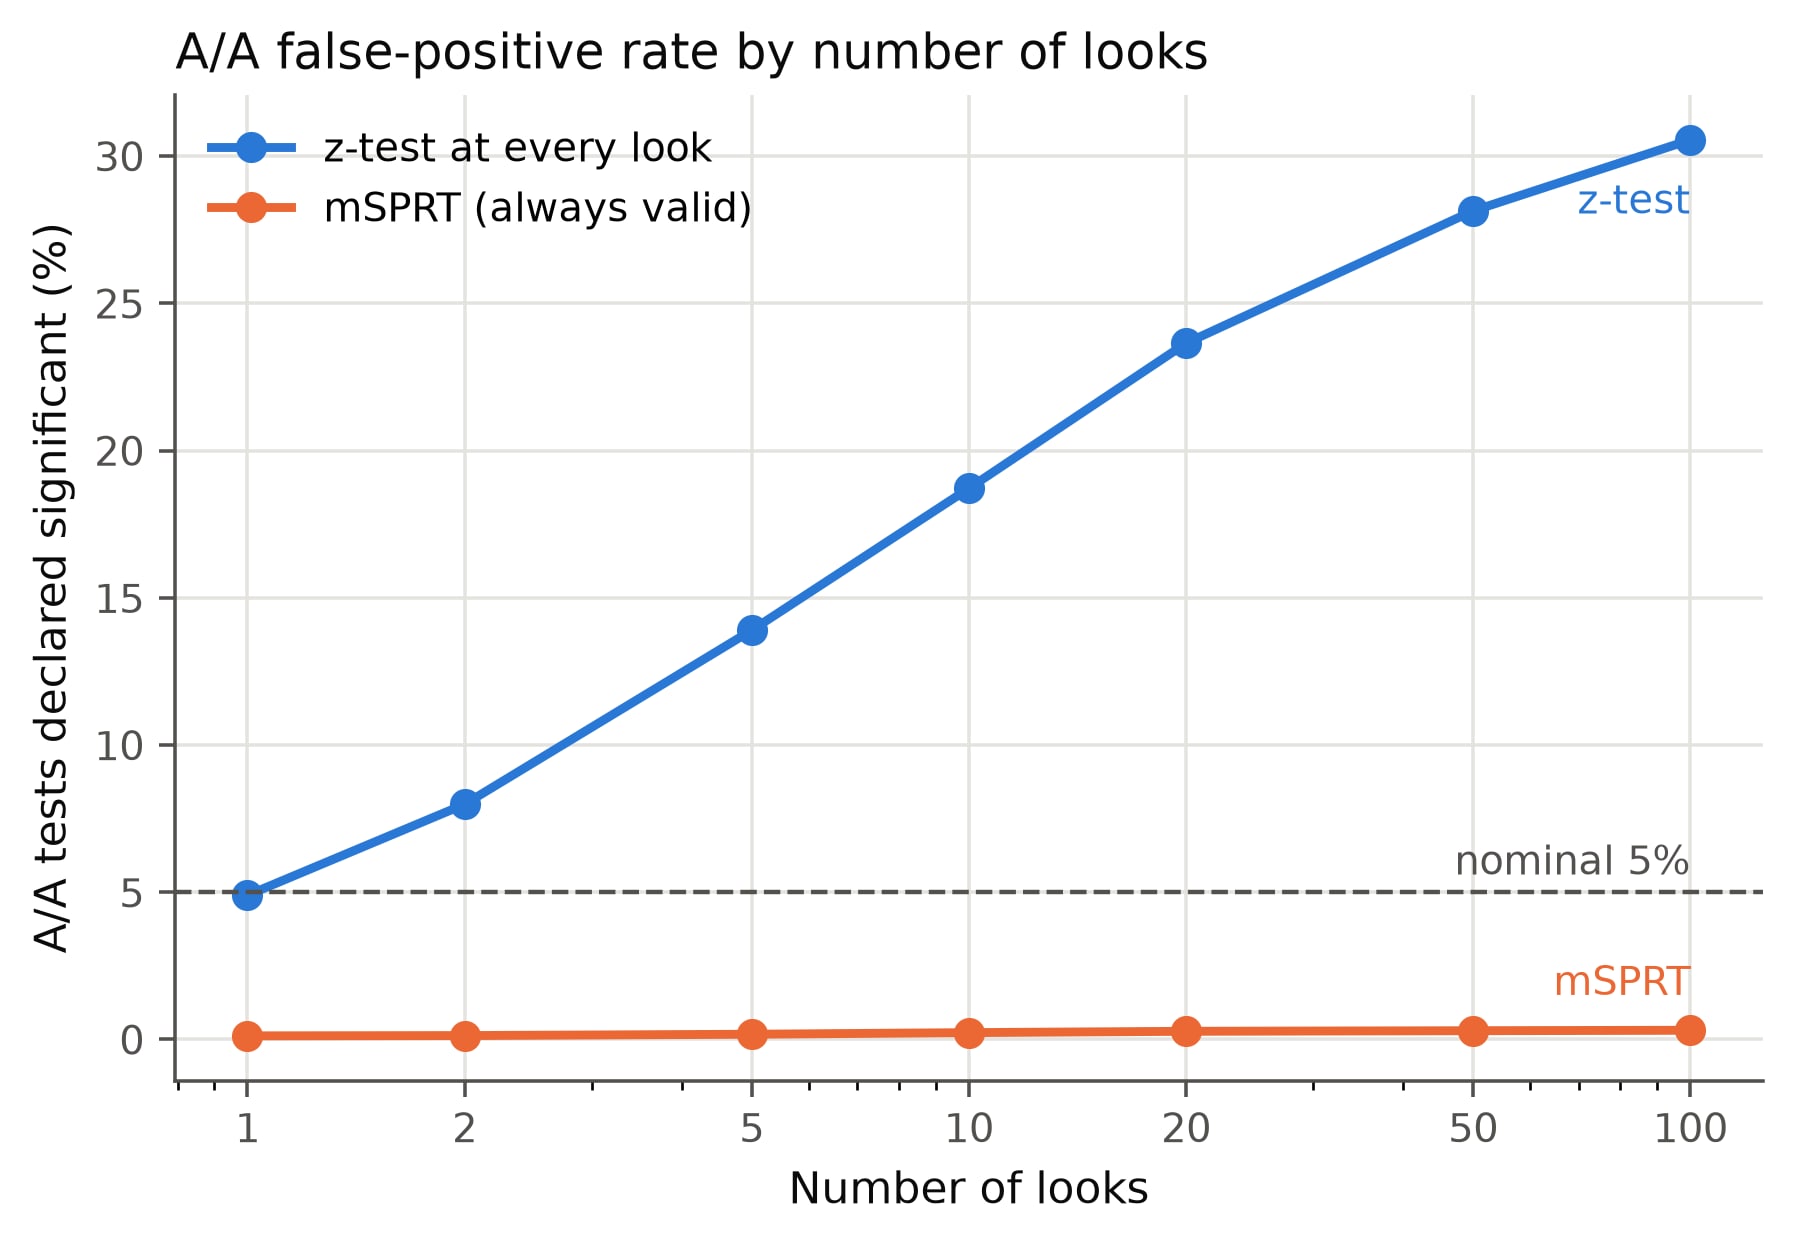
- 30.6%of simulated A/B tests with nothing to find called a winner after 100 looks
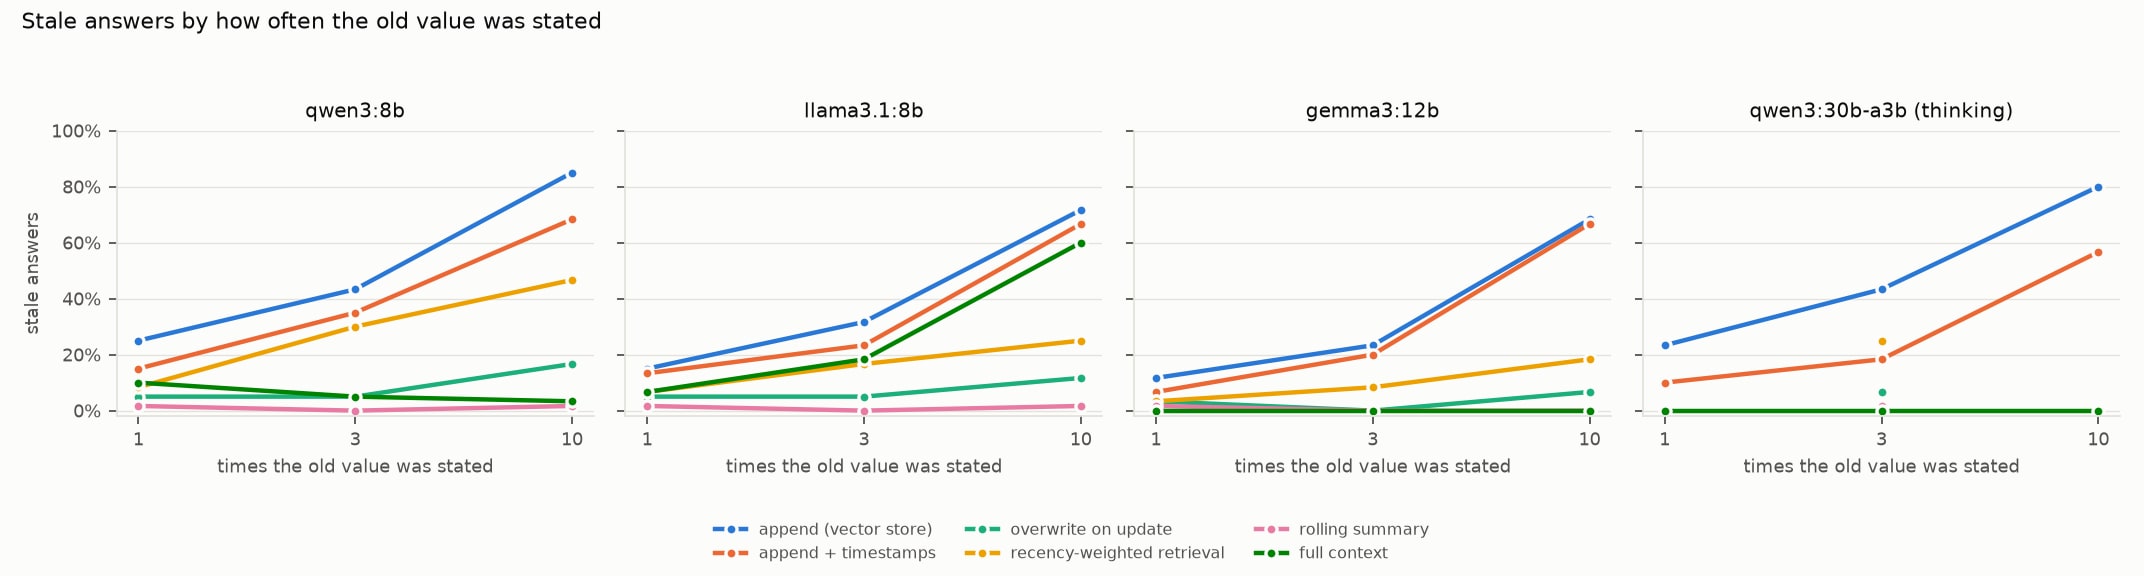
- +57–60 ptsmore stale answers from agent memory when an old fact was said ten times, not once
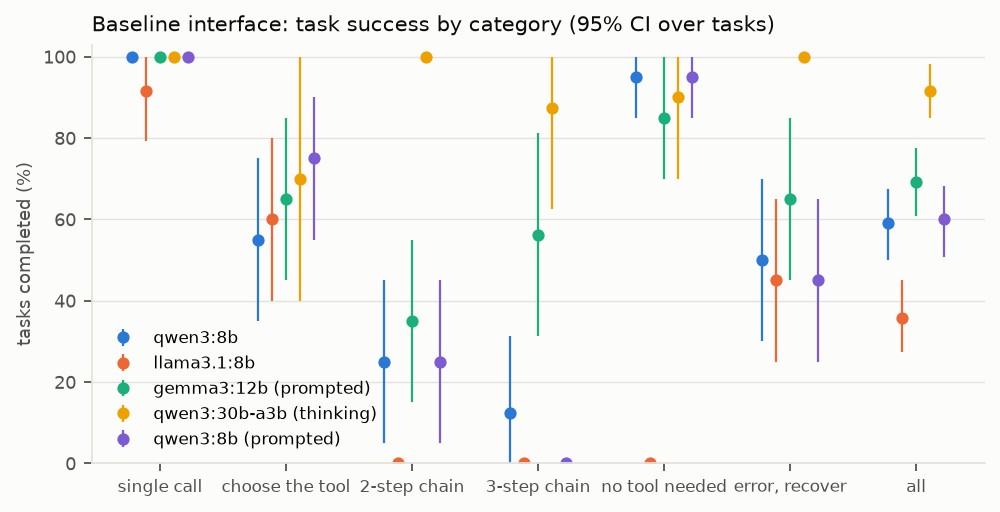
- 0–35%of two-step tool chains finished by three local models that got 92–100% of single calls right
Measured, not argued
Most claims about how AI systems break are a screenshot of one bad answer. These put a number on one failure at a time, with the same rules each time: one factor at a time, a noise floor from a repeat run, and predictions written down before the full run.
The series: Measuring LLM SystemsHow often does checking early find a winner that isn't there?
Both versions of the test are identical, so every winner is a false one. It should be 5%.
20,000 simulated tests at real headline-test sizes · how it was measured
Three to start with
A product people used, a tool that agents call, and the tool I use to tell whether a change really helped.
Launch Plan
Real users · January – July 2026
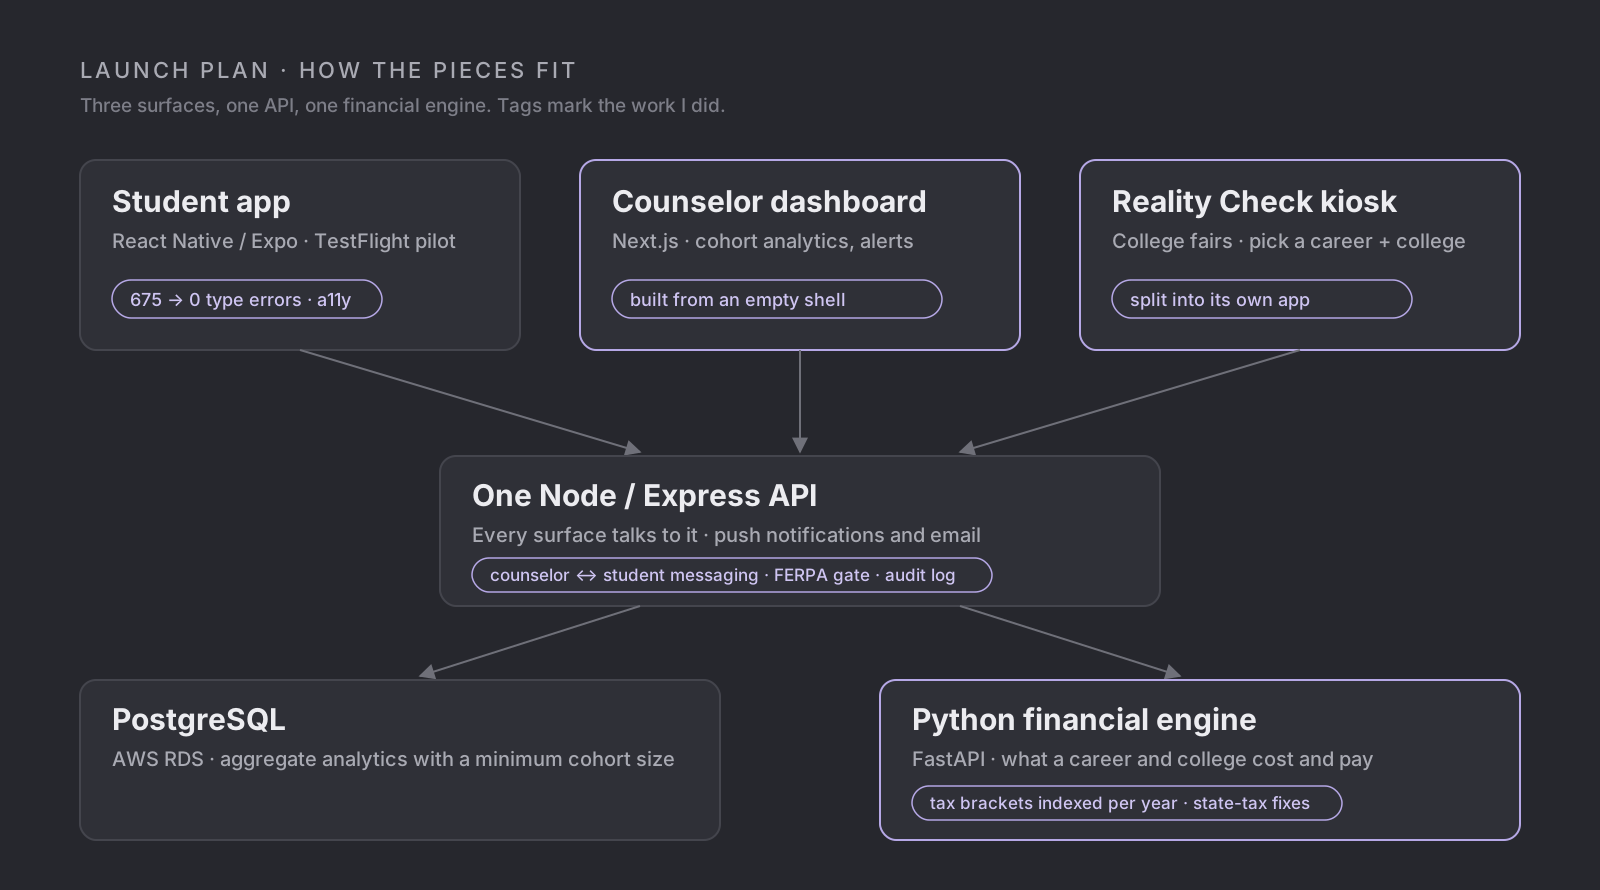
High-school students pick colleges and careers without seeing what those choices will cost and earn.
The school side was ready for a pilot, with a runbook for school admins and counselors, and 25 security and correctness findings closed, 2 of them critical.
- audit findings closed
- 25audit findings closed
- commits, January to July
- ~130commits, January to July
bostonmove
A tool agents call · October 2026
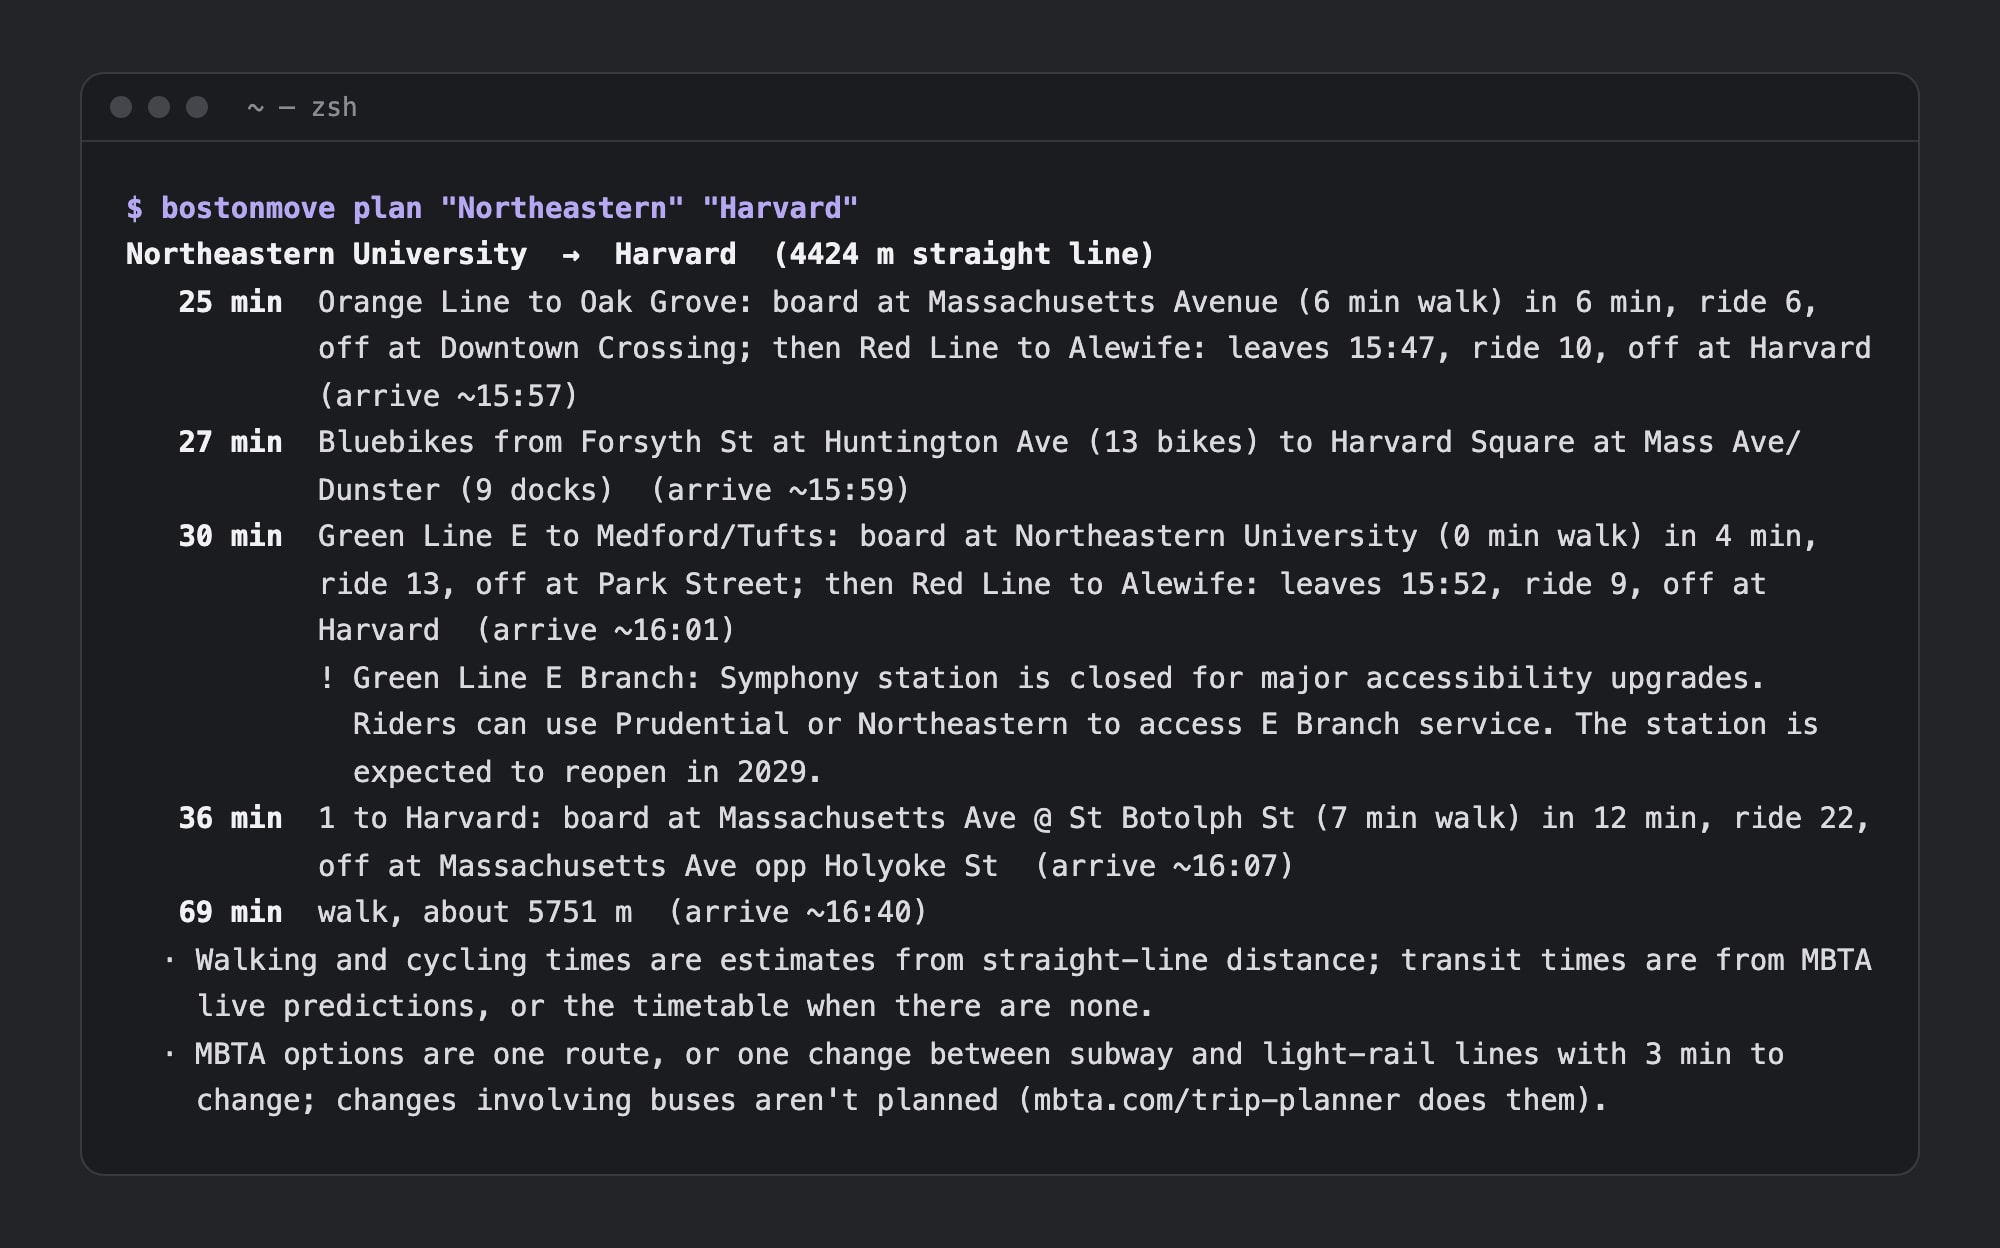
Ask a coding agent when the next Red Line train is and it guesses. The real answer is public, but it's split across the MBTA's API, the Bluebikes feed and a geocoder, each with its own IDs, limits and licence terms.
On PyPI and the official MCP registry. A version tag publishes to both, with no stored token or login. 36 offline tests replay 57 recorded real responses with the clock frozen.
- MBTA requests per trip plan
- 4–16MBTA requests per trip plan
- recorded real responses the tests replay
- 57recorded real responses the tests replay
evalpair
Did the change help? · November 2026
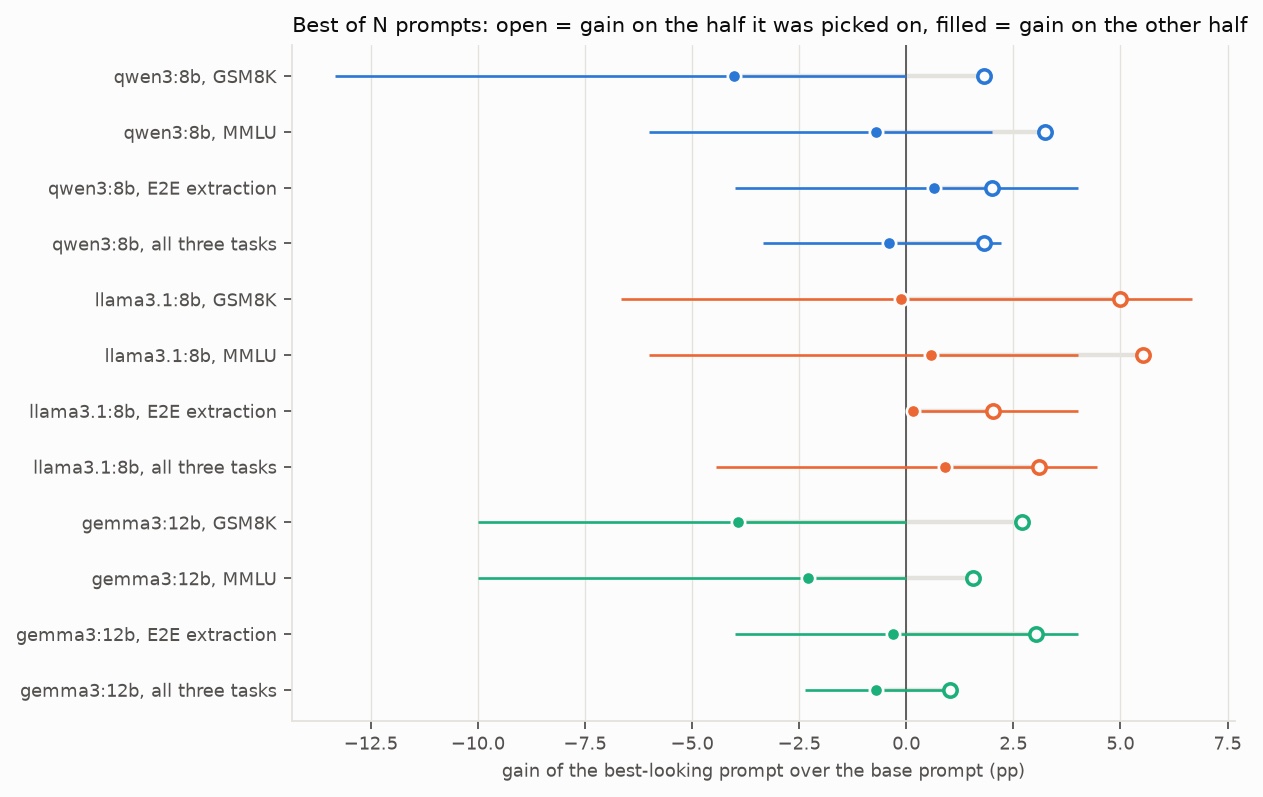
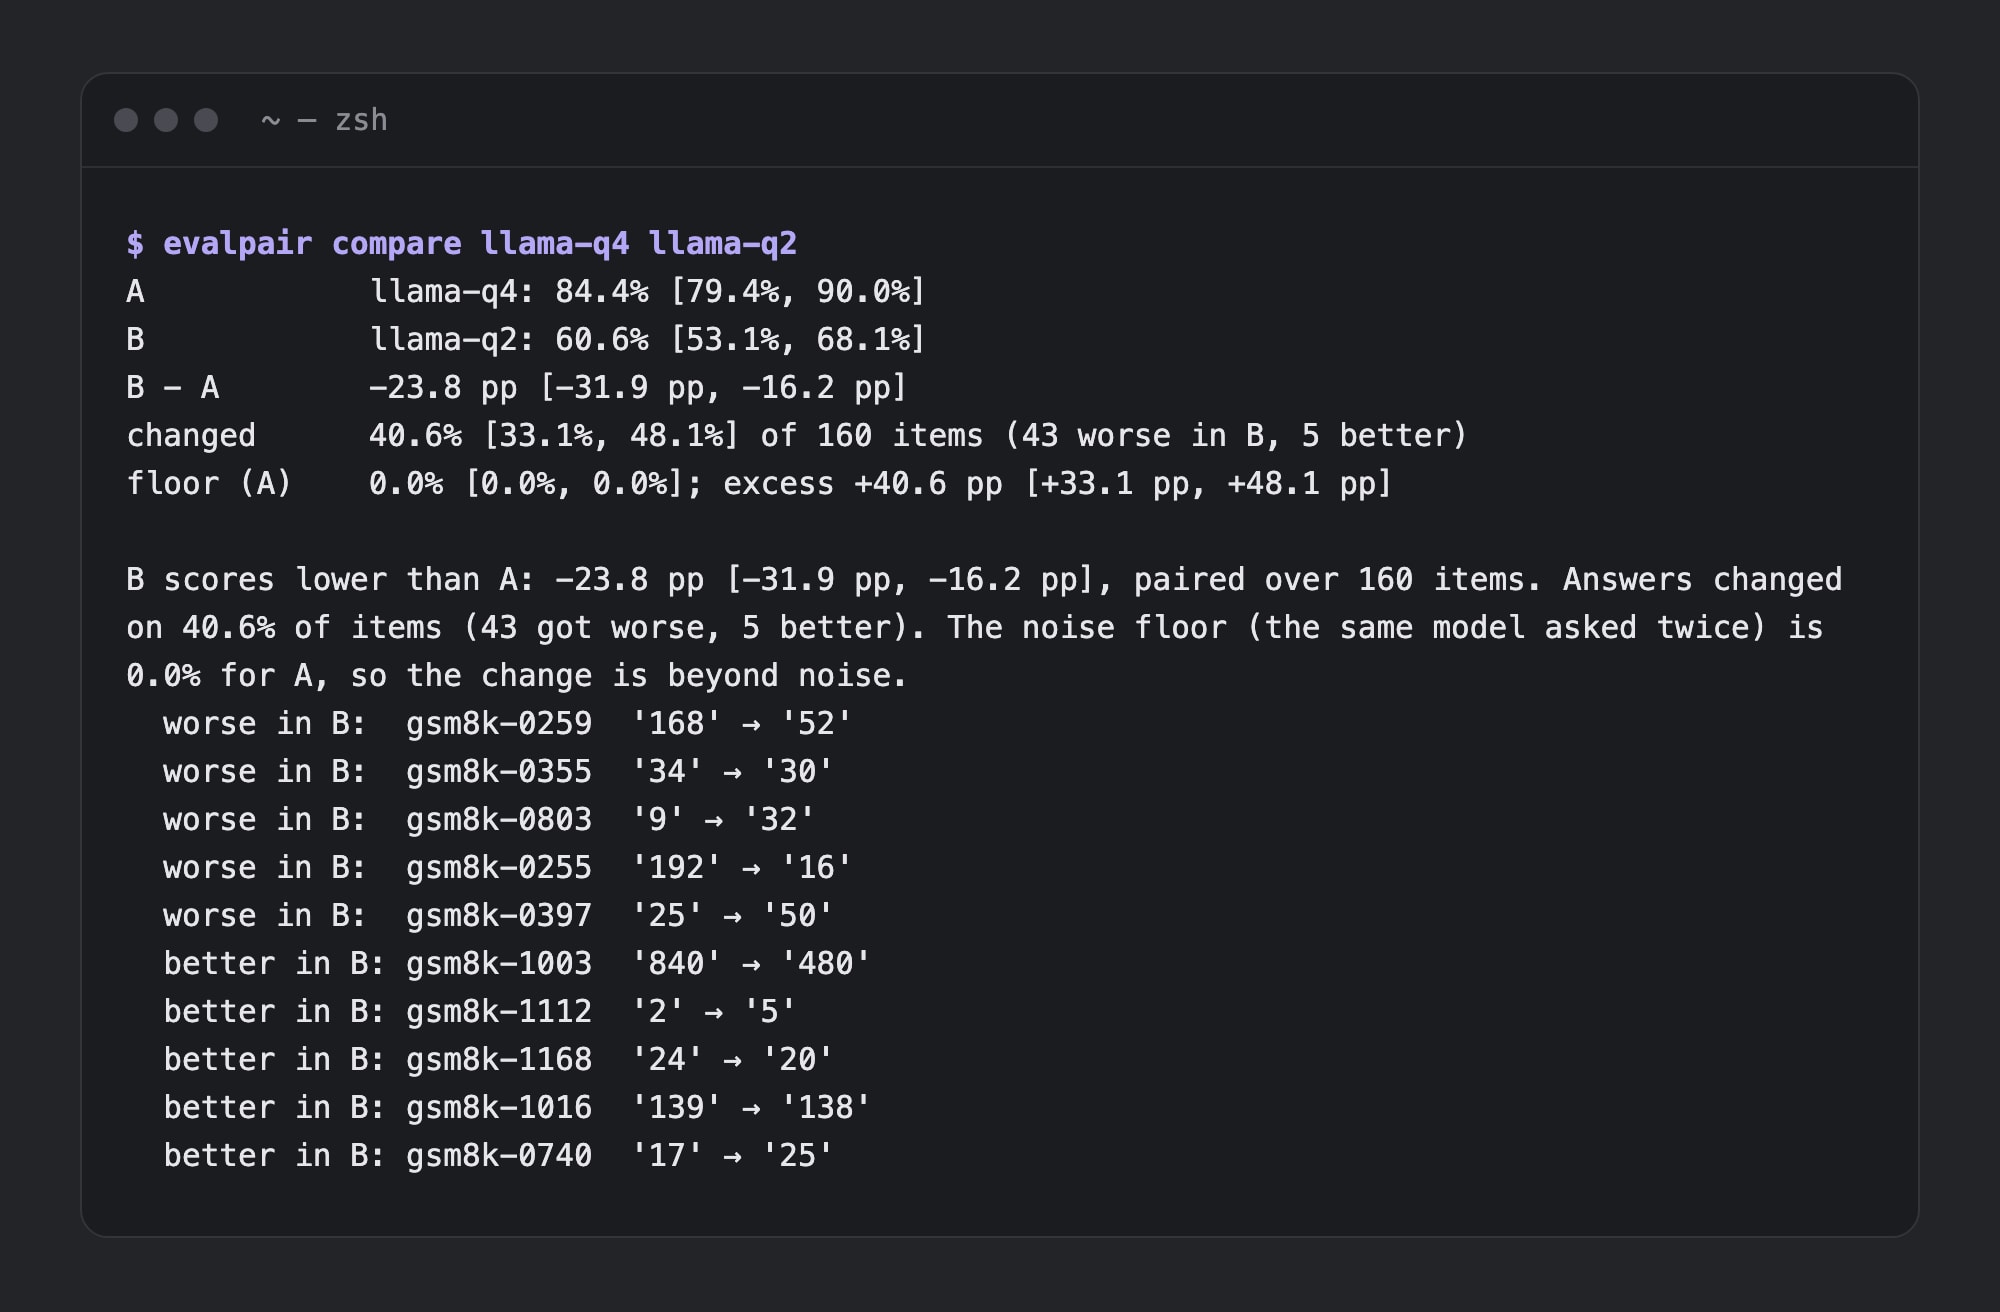
Most eval tools print two scores side by side, and a 2-point gap on 160 questions looks like a result when it usually isn't. Across my studies, the same mistake kept costing time: reading a difference without an interval, or without knowing how much the model moves on its own.
On PyPI and the official MCP registry. Its first real run reproduced the quantization study's scores exactly, and its checkers re-scored all 9,870 of that study's replies the same way. That run also caught a parsing bug two of my studies shared.
- study replies re-scored, every one the same
- 9,870study replies re-scored, every one the same
- items in the three bundled suites
- 470items in the three bundled suites
More work
All projects- Silent RAG FailuresA benchmark that breaks RAG retrieval on purpose, then tests which label-free signals notice before users do. Northeastern capstone, team of four.
- Yeas & NaysEvery Boston City Council roll call since 2008, updated each morning from the City's pages, with the records that contradict their own tally flagged.
- KeystoneA reader that shows what a research paper builds on, disputes and takes on faith, quoted from its own LaTeX. Graded against outside labels, errors published.
- worksearchSearch over my 24 repos, and a test of whether fine-tuning the embedding model on my own history beats keyword search. It didn't; fusing the two did.
- diffnoteA 1.5B model LoRA-tuned on my commit history on a laptop. On repos it never saw, it writes subjects as close to the real ones as an untuned 8B model.
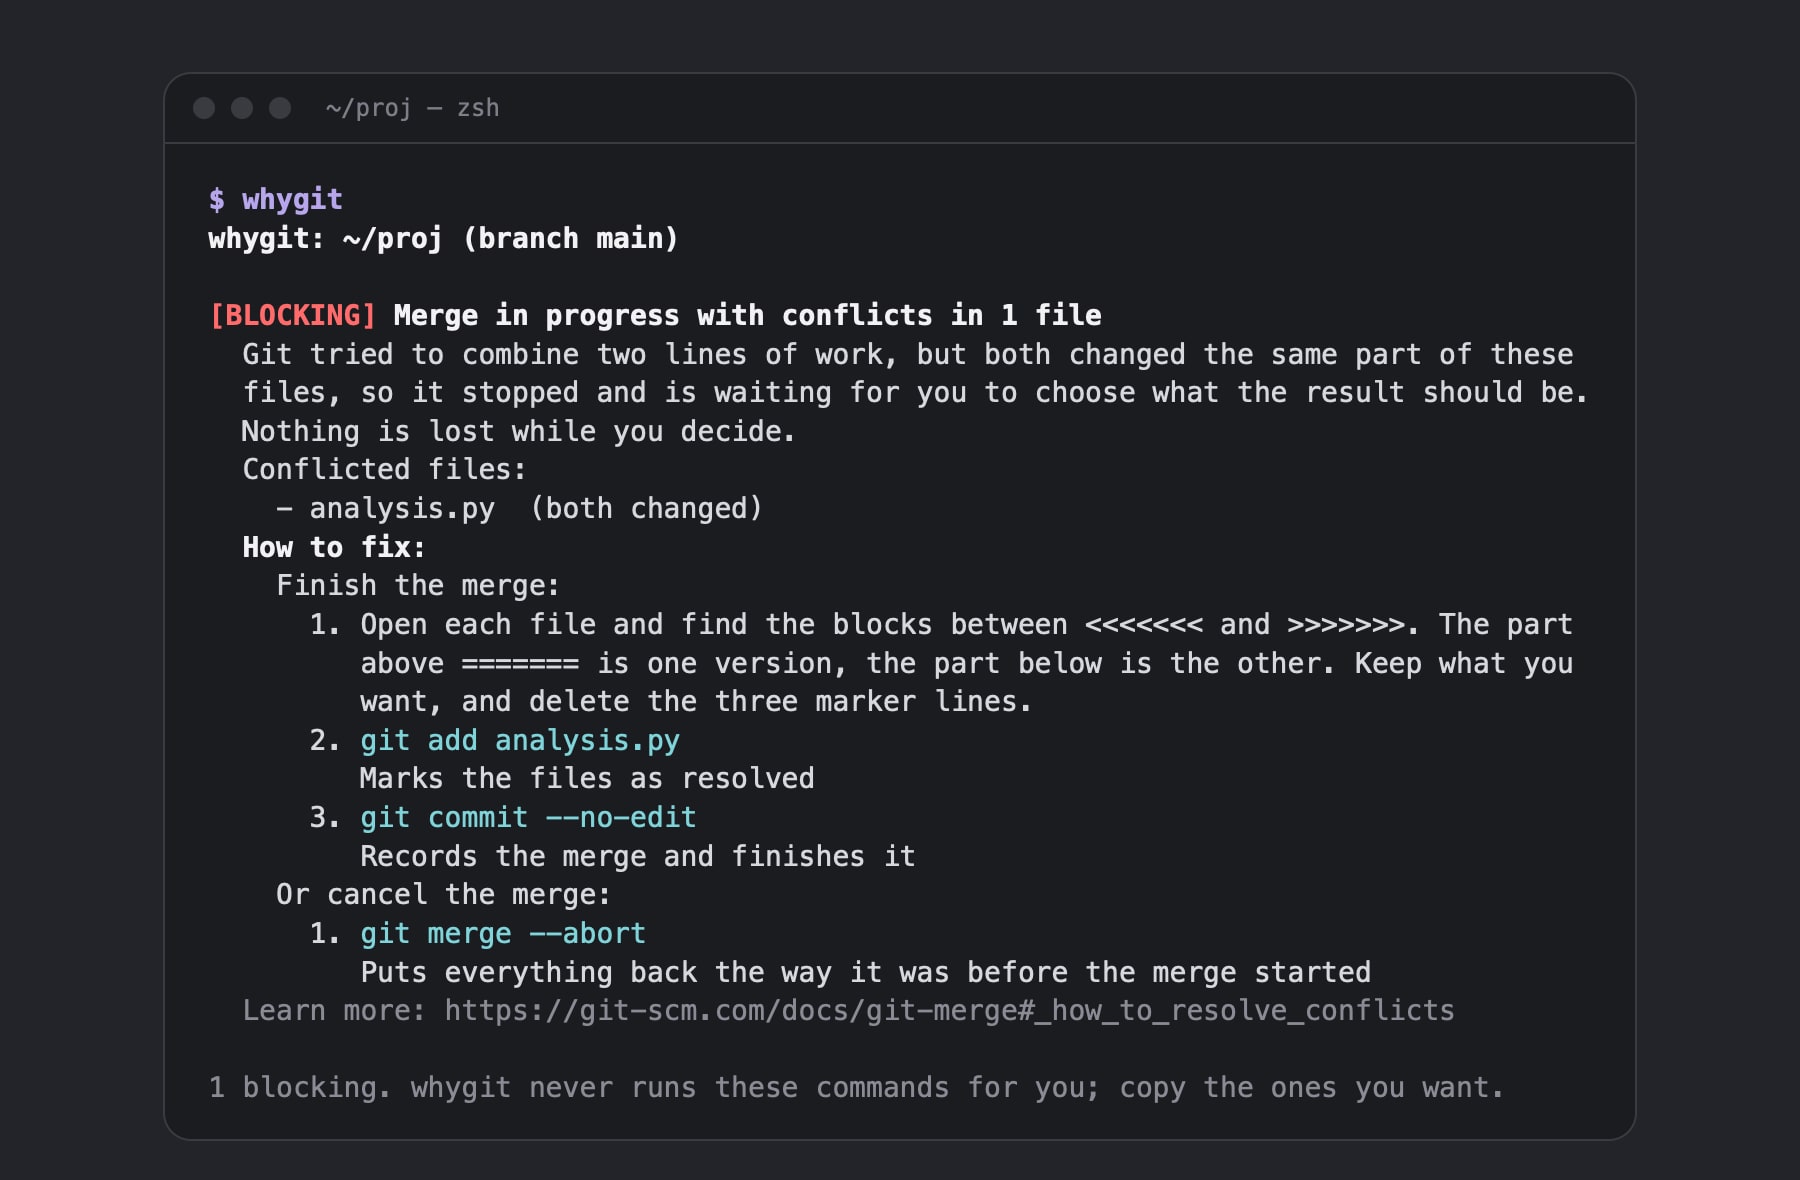
- whygitA read-only CLI and MCP server that explains a Git repository's state in plain English and gives the exact commands to fix it. On PyPI and the MCP registry.
- Experiment ForensicsA pre-registered re-analysis of 22,743 Upworthy A/B tests: how peeking, the winner's curse and low power change the answer. All 13 checks replicated.
- AURORAAURORA's 41% calibration gain was a units bug. The audit, and the paper it became: region-aware GPs should adapt the noise, not the approximation.
Experience
Full historySeptember 2026 - Present
Teaching Assistant, DS 3500: Advanced Programming with Data · Northeastern University
- Teaching assistant for DS 3500, Advanced Programming with Data, a class of 108 students, working with Professor Deahan Yu.
- The course covers data pipelines, modelling, caching with Redis and building apps in Streamlit.
- Hold office hours and run checkoff meetings, where each student walks me through a small project so I can check they understand how it works; I also help with the class quizzes.
- Helped the class through Git for the first time, from installing and authenticating to their first merge conflicts.
January 2026 - July 2026
Data Scientist · Launch Plan
- Built the school side of a K-12 financial-literacy platform whose student app went into a TestFlight pilot: a counselor dashboard from an empty Next.js shell, with cohort analytics behind a privacy floor and FERPA-gated messaging to students over push and email, and Reality Check, a college-fair kiosk that shows students what a career and college choice really cost.
- Built LangGraph workflows and MCP server integrations that let LLM agents write and tailor lessons with internal tools and outside APIs, taking content formatting and assessment assembly off the teaching team.
- Replaced a keyword search educators didn't trust with a RAG pipeline on Pinecone and custom embedding models, fed by a data layer built with FastAPI, PostgreSQL and Airflow that pulls in content from several school districts.
- Led a security and correctness sweep before the pilot that closed 25 audit findings, 2 of them critical, as part of about 130 commits across the mobile app, API and data layer.
January 2026
Quantum Winter School (Mentee) · Massachusetts Institute of Technology
- A four-day program at MIT with about 50 participants, taught by instructors from MIT Physics, MIT CSAIL and Harvard SEAS.
- Went from qubits, quantum gates and entanglement to Bell's theorem, the CHSH inequality and algorithms such as Shor's.
- Built and ran quantum circuits in hands-on Qiskit labs and on the qBraid platform.
Latest writing
All writingGet in touch
Questions about my work, a role, or a project idea. Send a message here or email me directly.
Srikarmks@gmail.com