Things I've built, from research tools and AI agents to a racing game. Filter by area.
Projects
One Bad Passage in 10,000
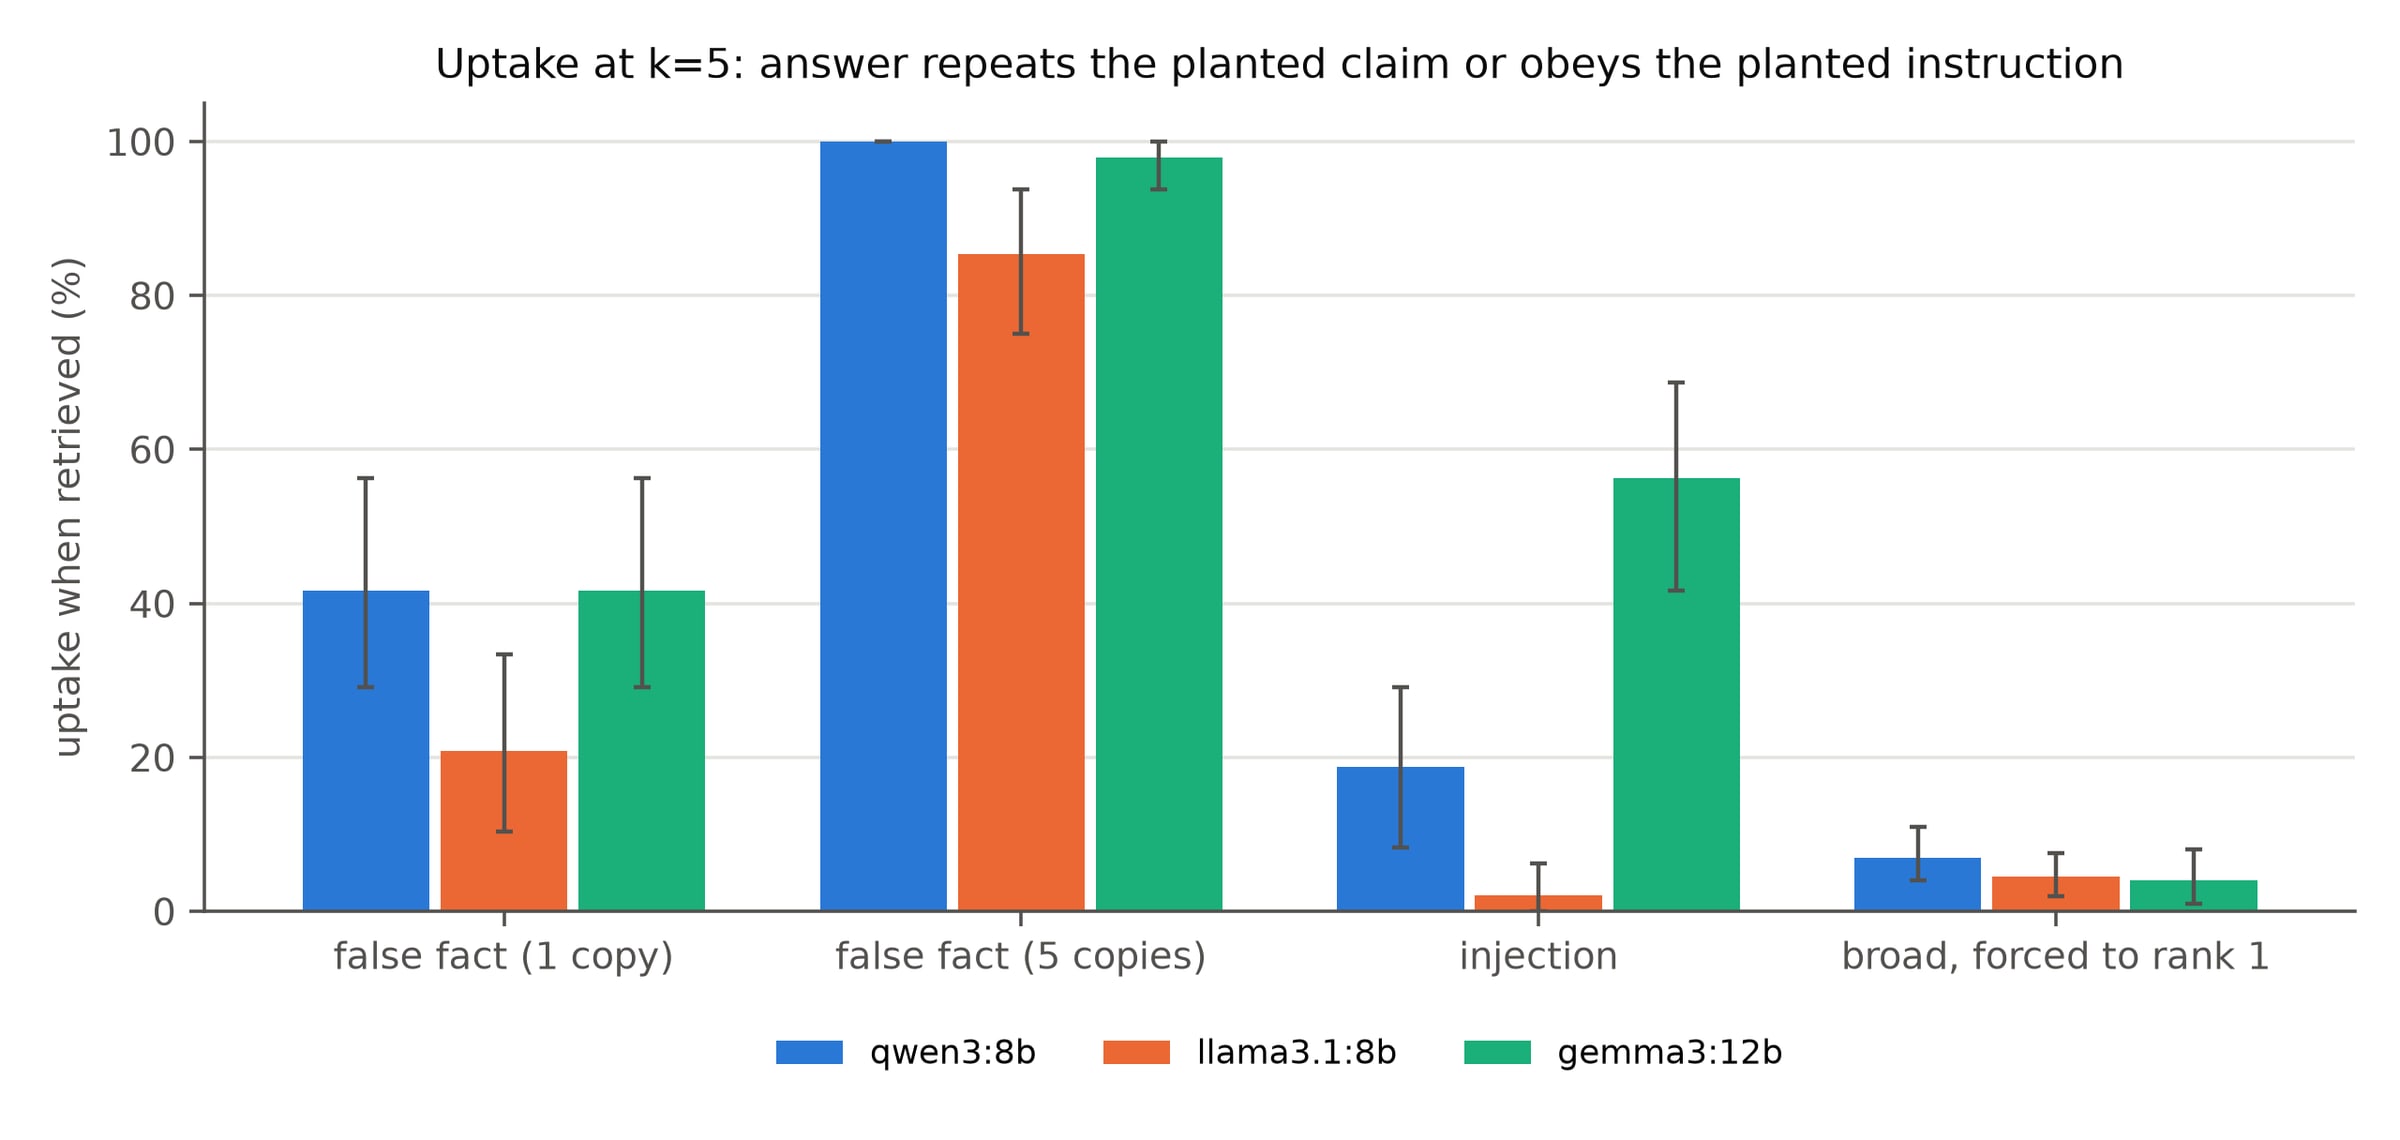
A retrieval-poisoning study: plant one false or malicious passage among 10,000 that a question-answering system reads from, and measure who it reaches, how often three open models repeat it, whether it spreads, and what simple defences cost in accuracy.
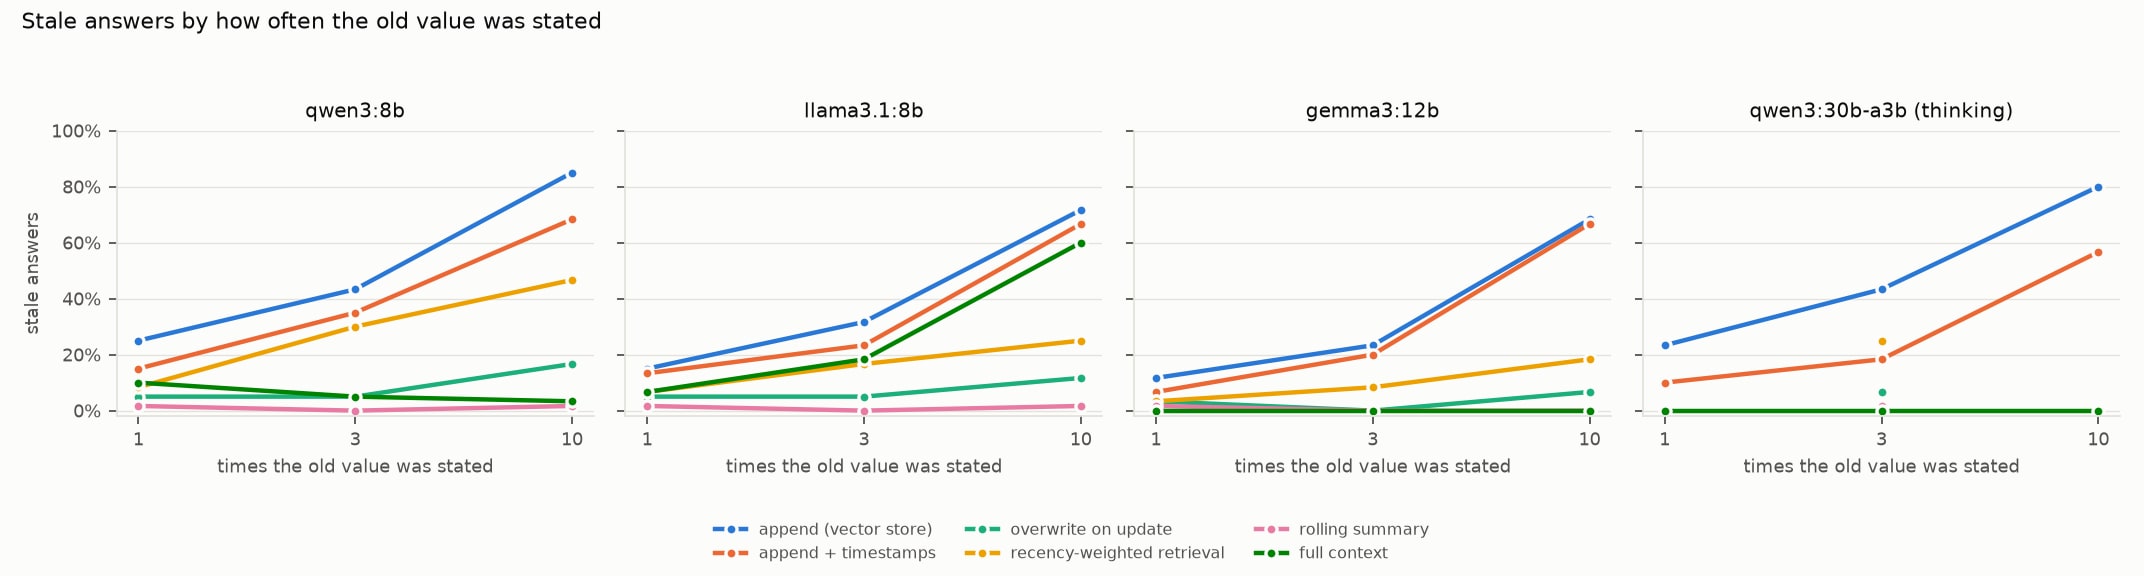
Do agents with long-term memory answer with an old fact after it changes? A controlled study across seven memory designs and four open models: repetition, not recency, drives stale answers, implied updates fool even full context, and overwriting or summarising fixes most of it at a cost.
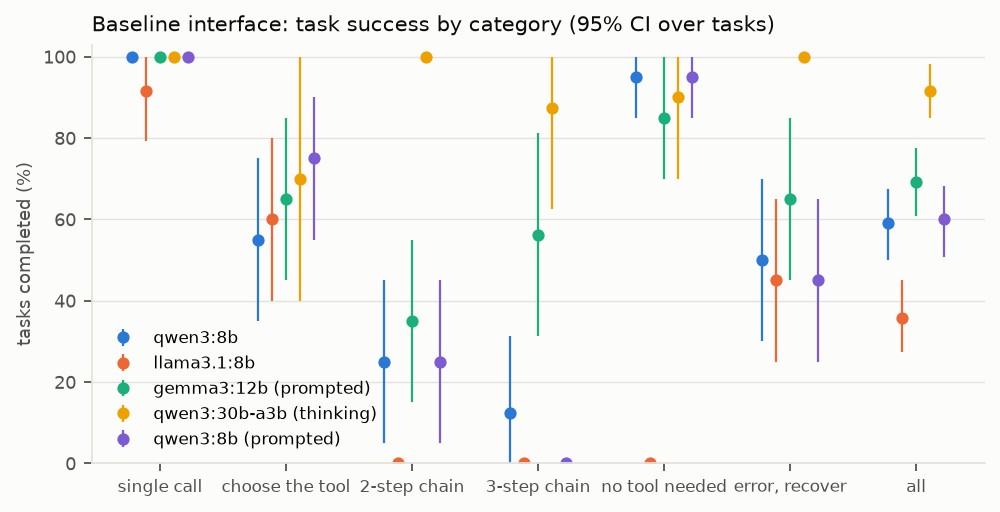
How reliably do local LLMs use tools? Three models made the right first call about 80% of the time but finished only 36–69% of tasks: they stopped after one step of a chain and reported errors they could fix. More tools, vague names and loose schemas barely mattered.
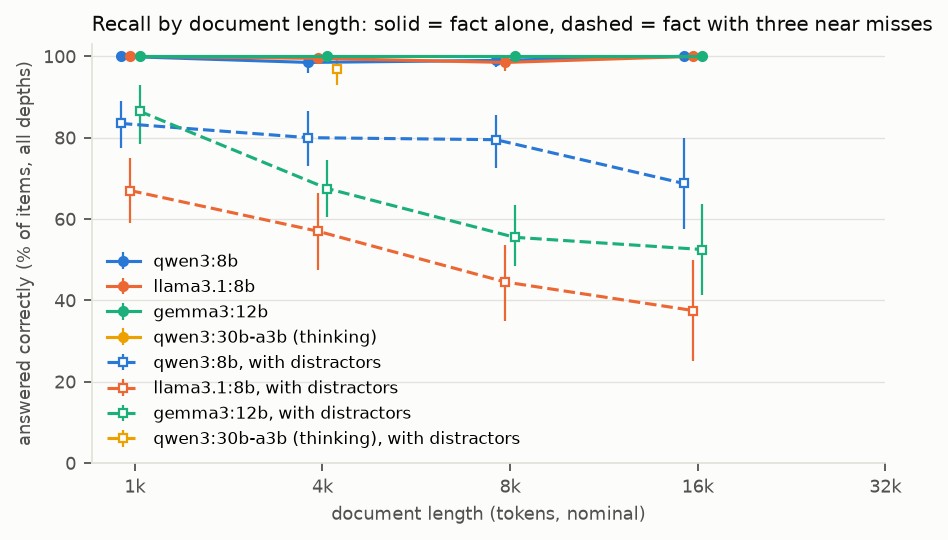
Can a local LLM find one fact in a long document? On its own, at any length up to 16k tokens. Among three look-alike facts, recall falls to 38–69% at 16k, wrong answers name a look-alike, and two facts far apart are often not combined.
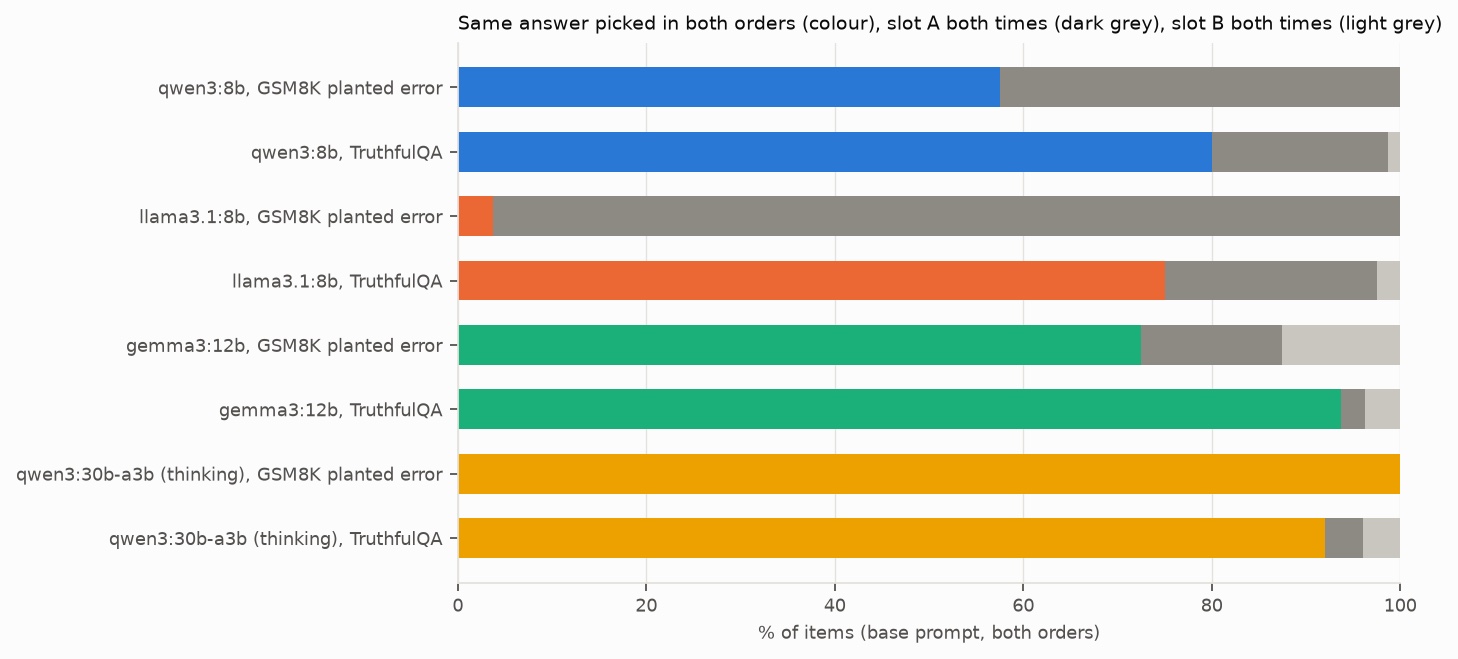
Do LLM judges grade on things that shouldn't matter? Three local models judged pairs with a known better answer: one picked whichever answer came first on 96% of maths pairs, padding a wrong answer helped it, stated confidence hurt, and two of three judges preferred their own work.
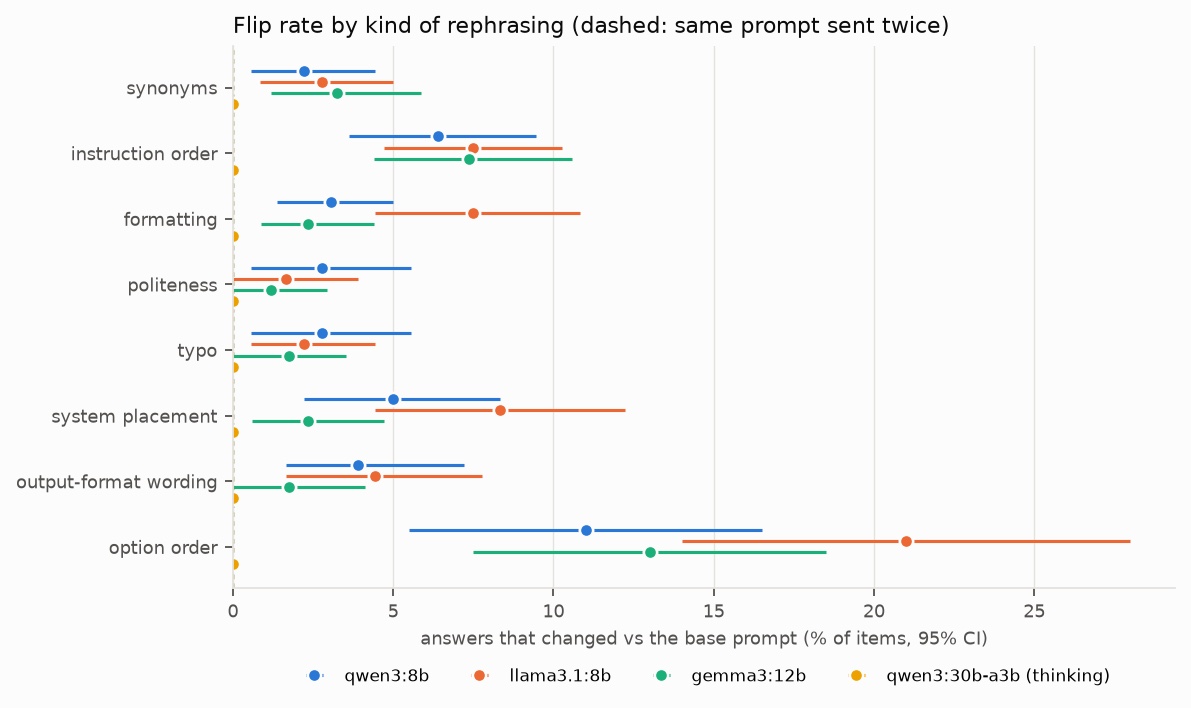
How often does a harmless rewording change an LLM's answer? 300 maths, multiple-choice and extraction items on three local models, plus a 30B thinking model: 5–8% of answers move per rephrasing, shuffled options move the most, and the best-looking prompt doesn't hold up on new items.
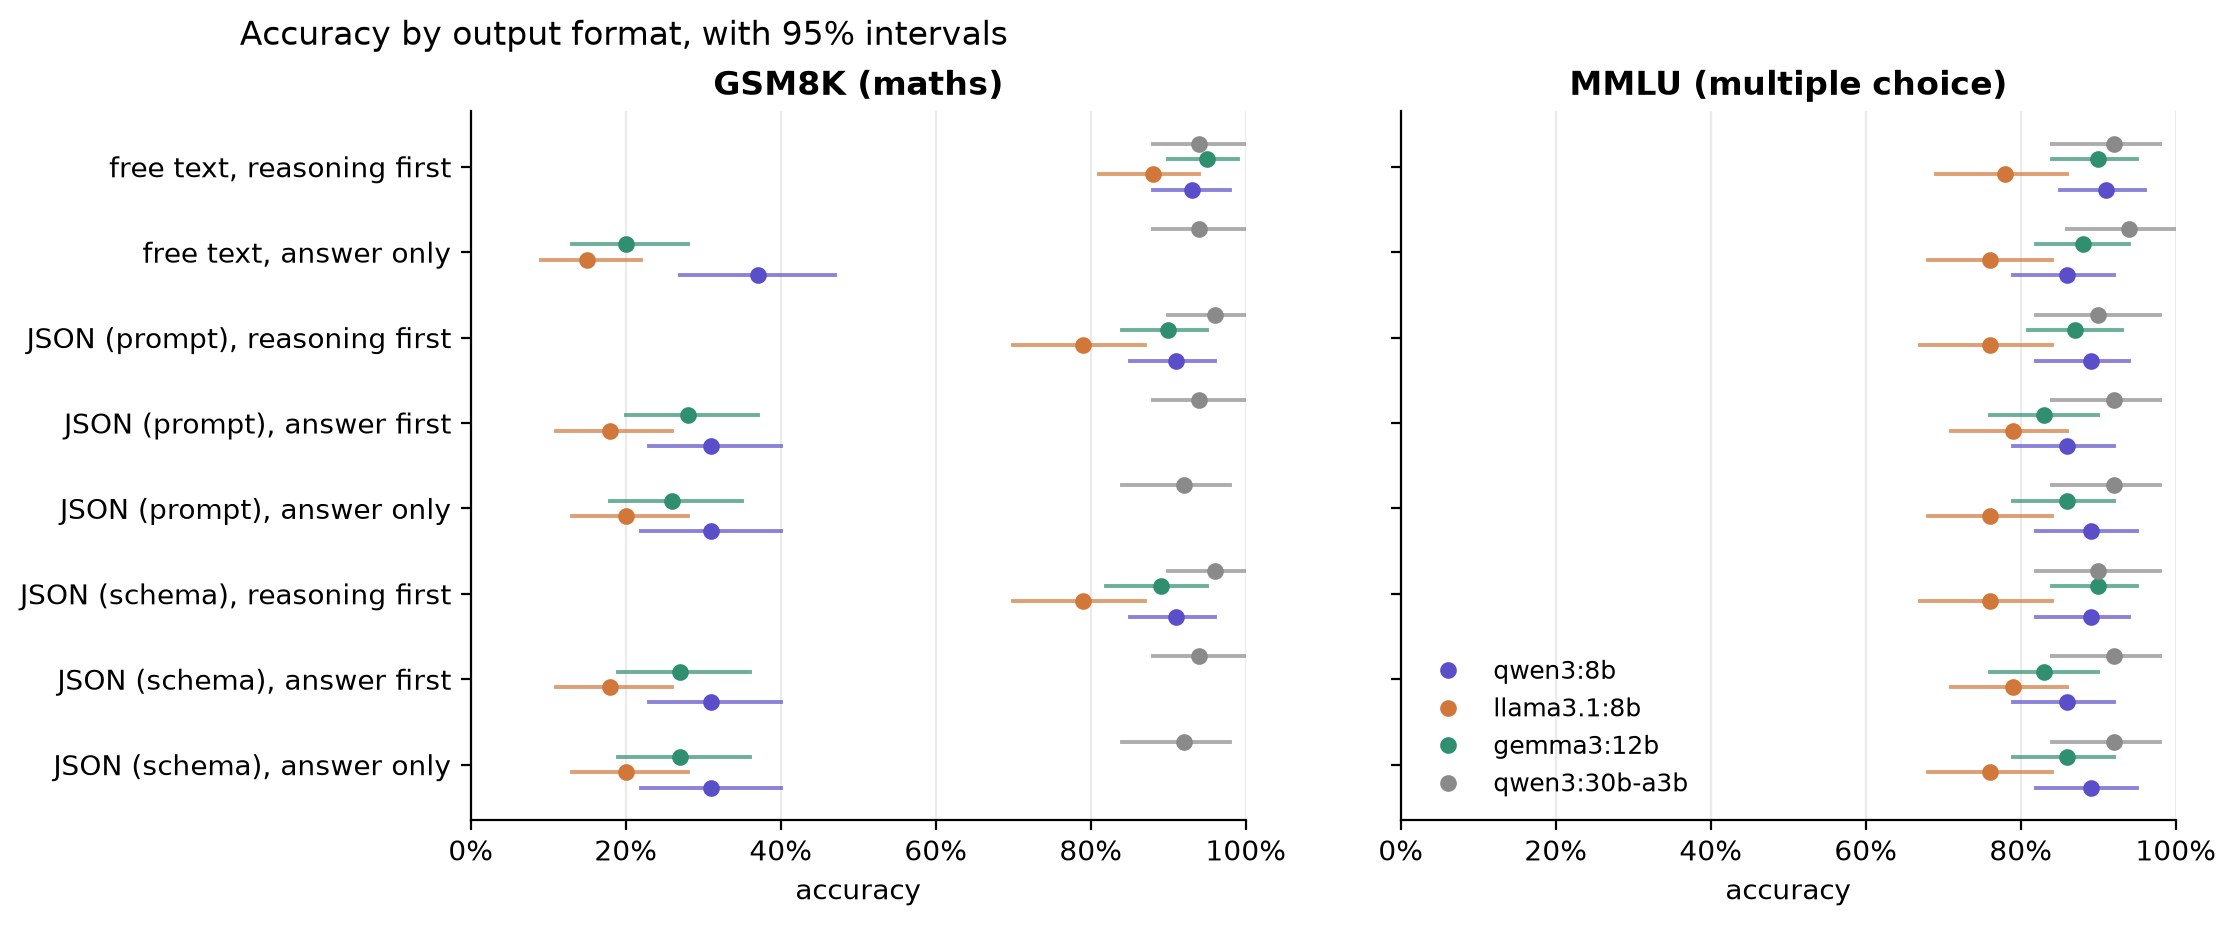
Does asking an LLM for JSON cost accuracy? 200 maths and multiple-choice items under eight output formats, plus 150 records extracted from drifting sources: JSON with the reasoning first costs 2–9 points, the answer first costs about 60, and schema-constrained decoding guarantees the format without changing the answers.
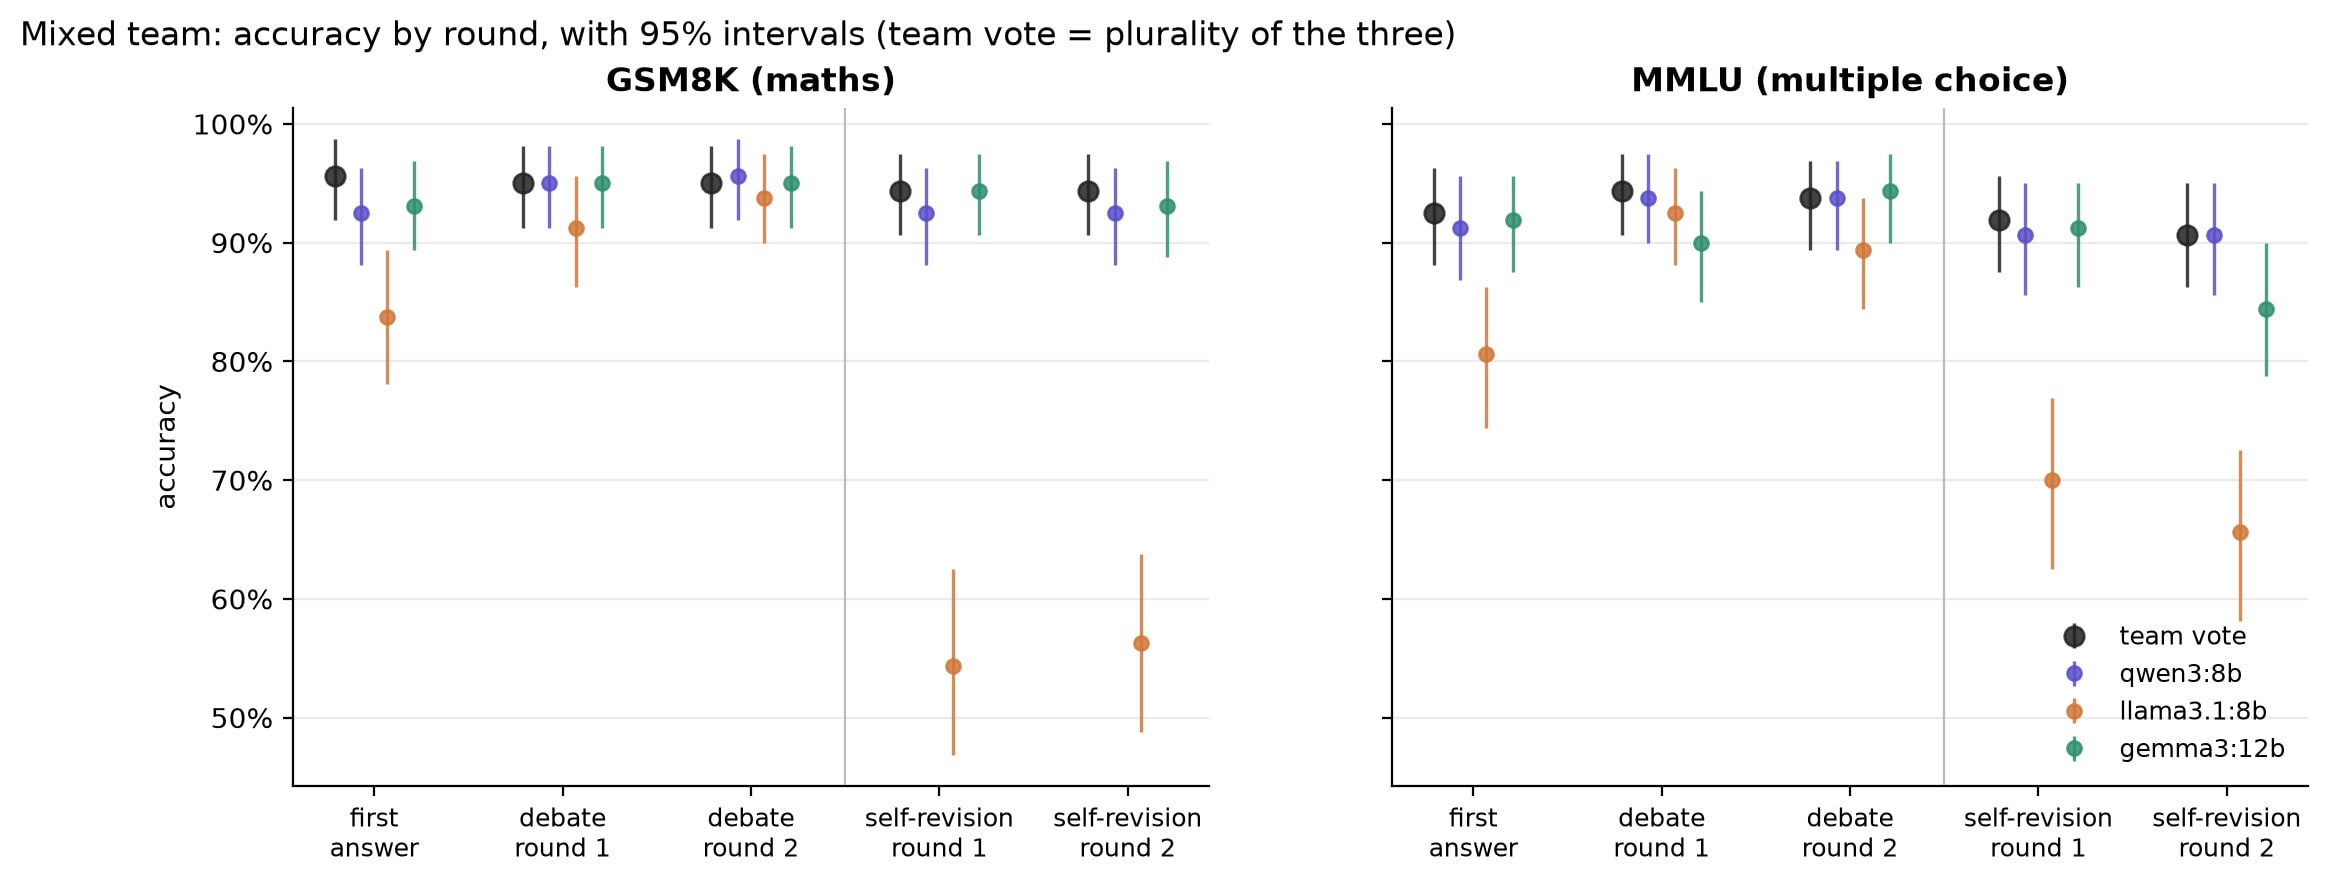
Do LLM agents that debate beat a plain vote? Three local models on 320 maths and multiple-choice questions: debate added 0.3 points over the vote, asking one model to check its own work cost it 27 points on maths, and two fake peers stating a wrong answer flipped a right agent 18.5% of the time.
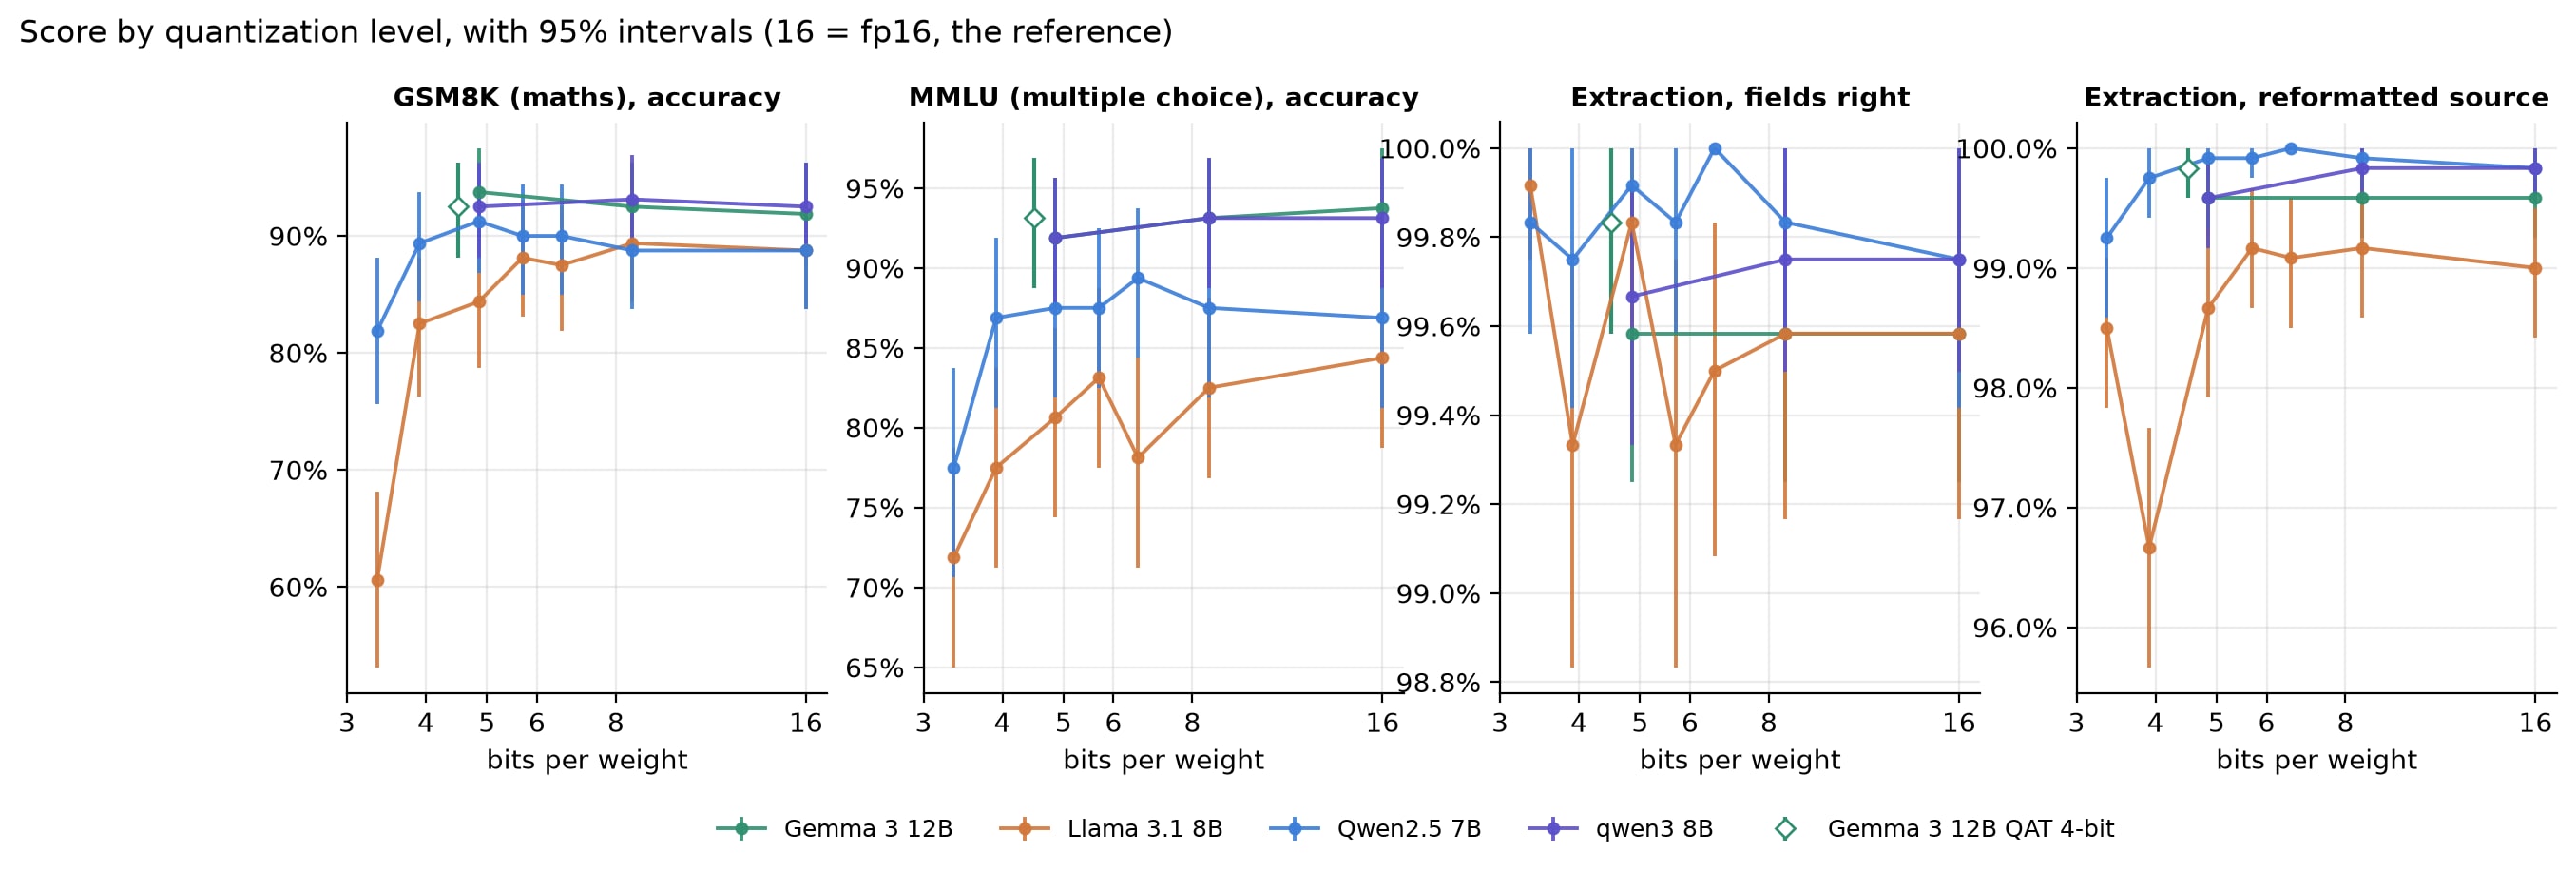
At what bit-width does a quantized LLM stop working? 21 builds of four local models, fp16 to 2-bit, on maths, multiple choice and JSON extraction: 5 bits and up is free, the 4-bit default nearly so, and at 2 bits one model loses 28 points on maths while another of the same size loses 7.
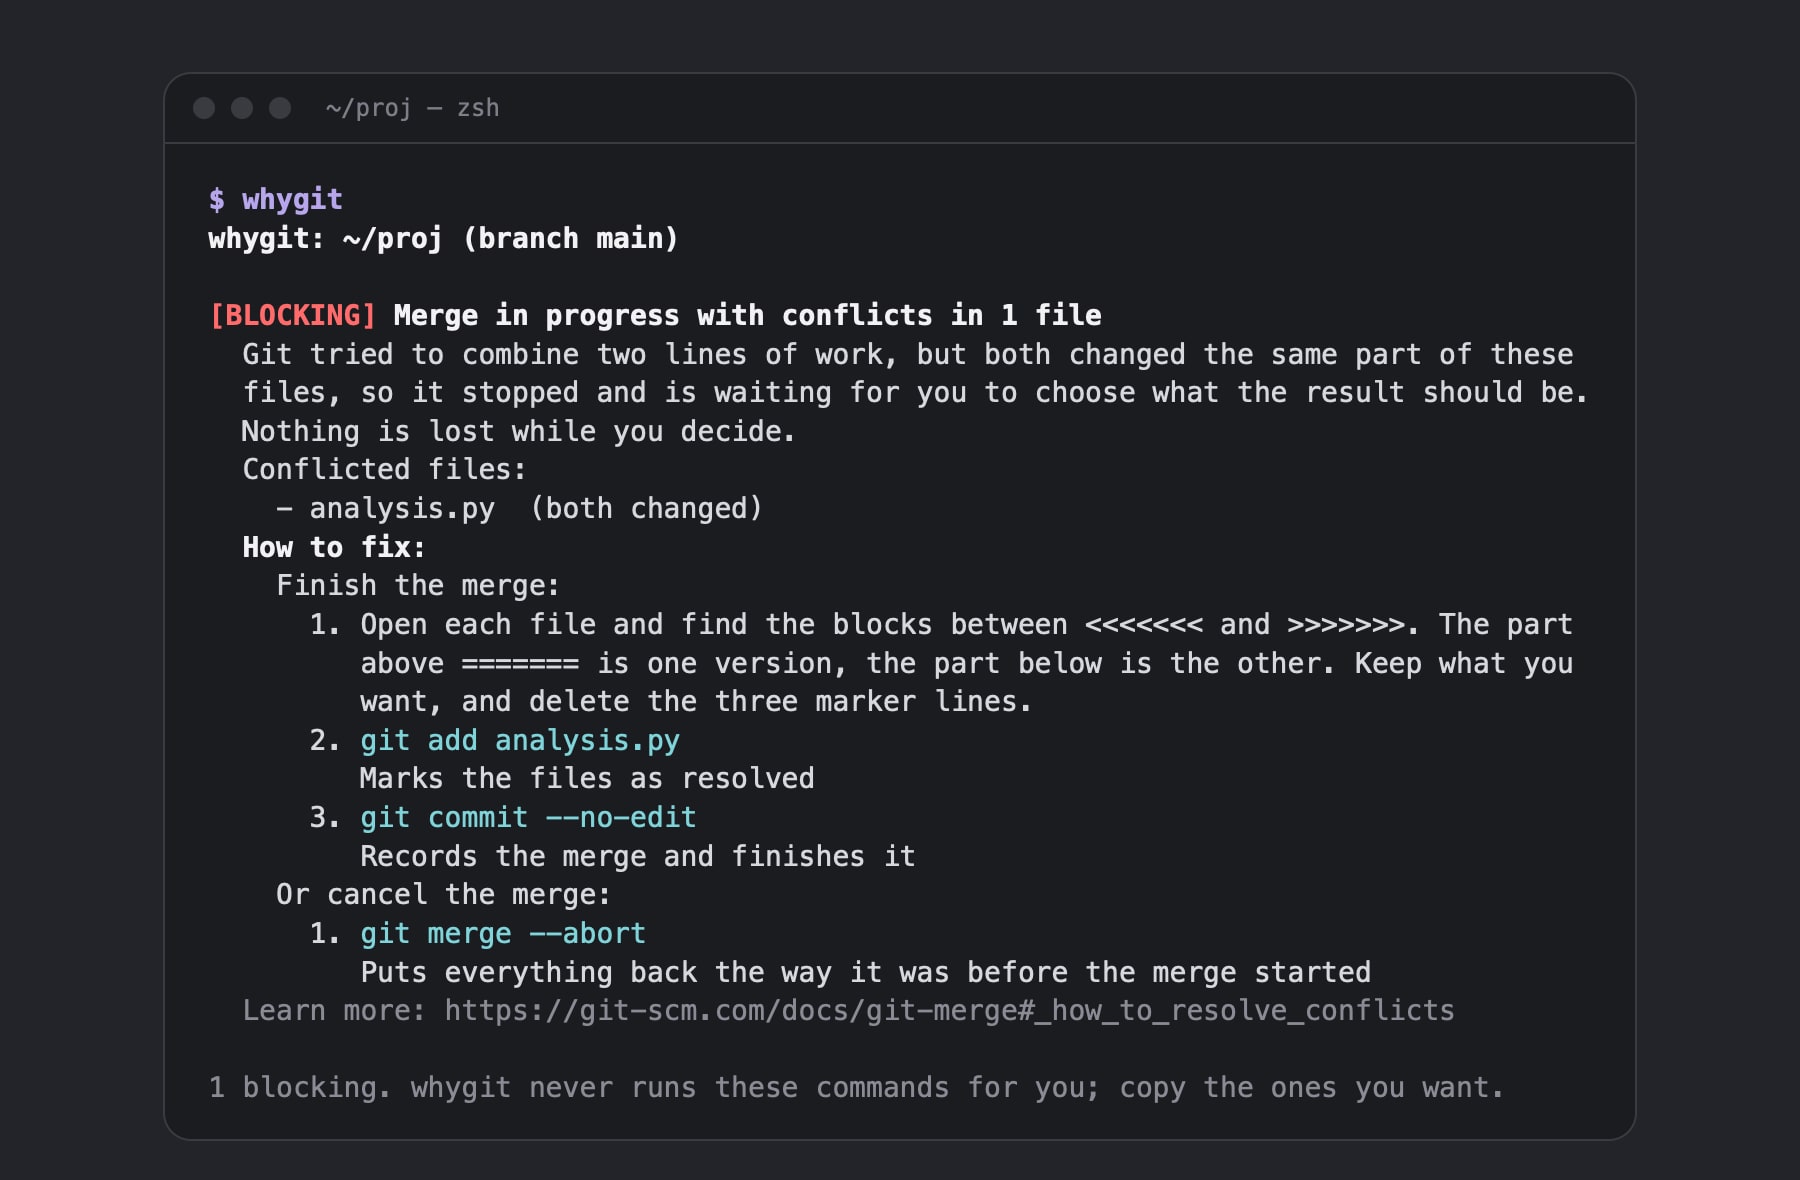
Looks at a Git repository and says in plain English what state it's in and how to fix it: merge conflicts, a rebase stopped halfway, a rejected push, a 100 MB CSV about to be committed. A command-line tool and an MCP server for coding agents, on PyPI. It never changes the repository, and the tests prove it.
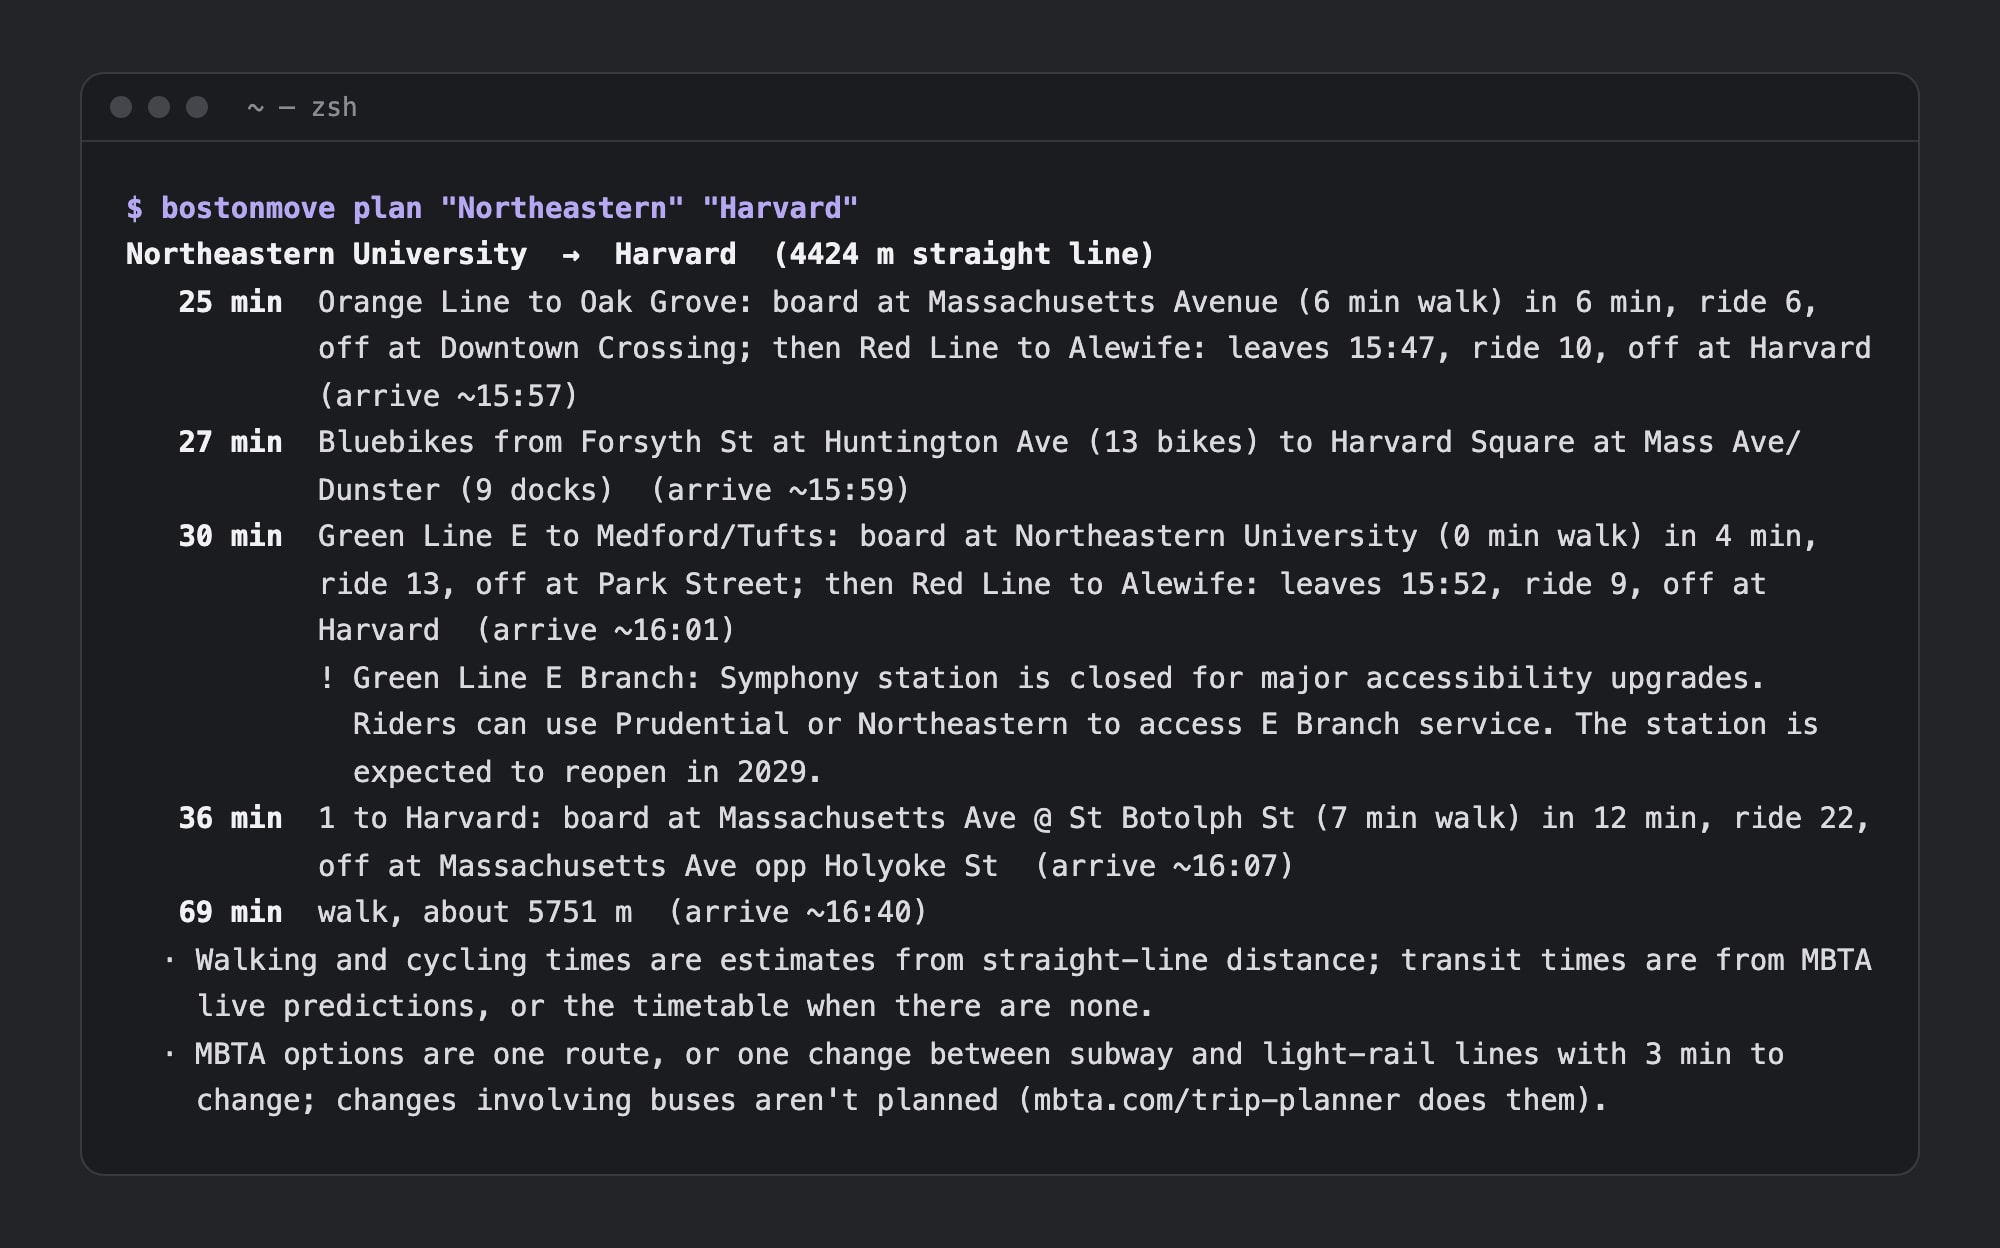
Getting around Boston from live public data: MBTA departures and service alerts, Bluebikes bike and dock counts, and door-to-door options by foot, bike or train, including one change between subway lines. A command-line tool and an MCP server, so coding agents answer with real numbers instead of guessing. On PyPI and the MCP registry.
A 1.5B code model LoRA-tuned with MLX on my laptop, on 469 commits from my own repos, to write the subject line for a staged change. On six repos it never saw it beats the untuned model by 5.8 points, still beats it with a style prompt, and ties an untuned 8B model in under a second per commit.
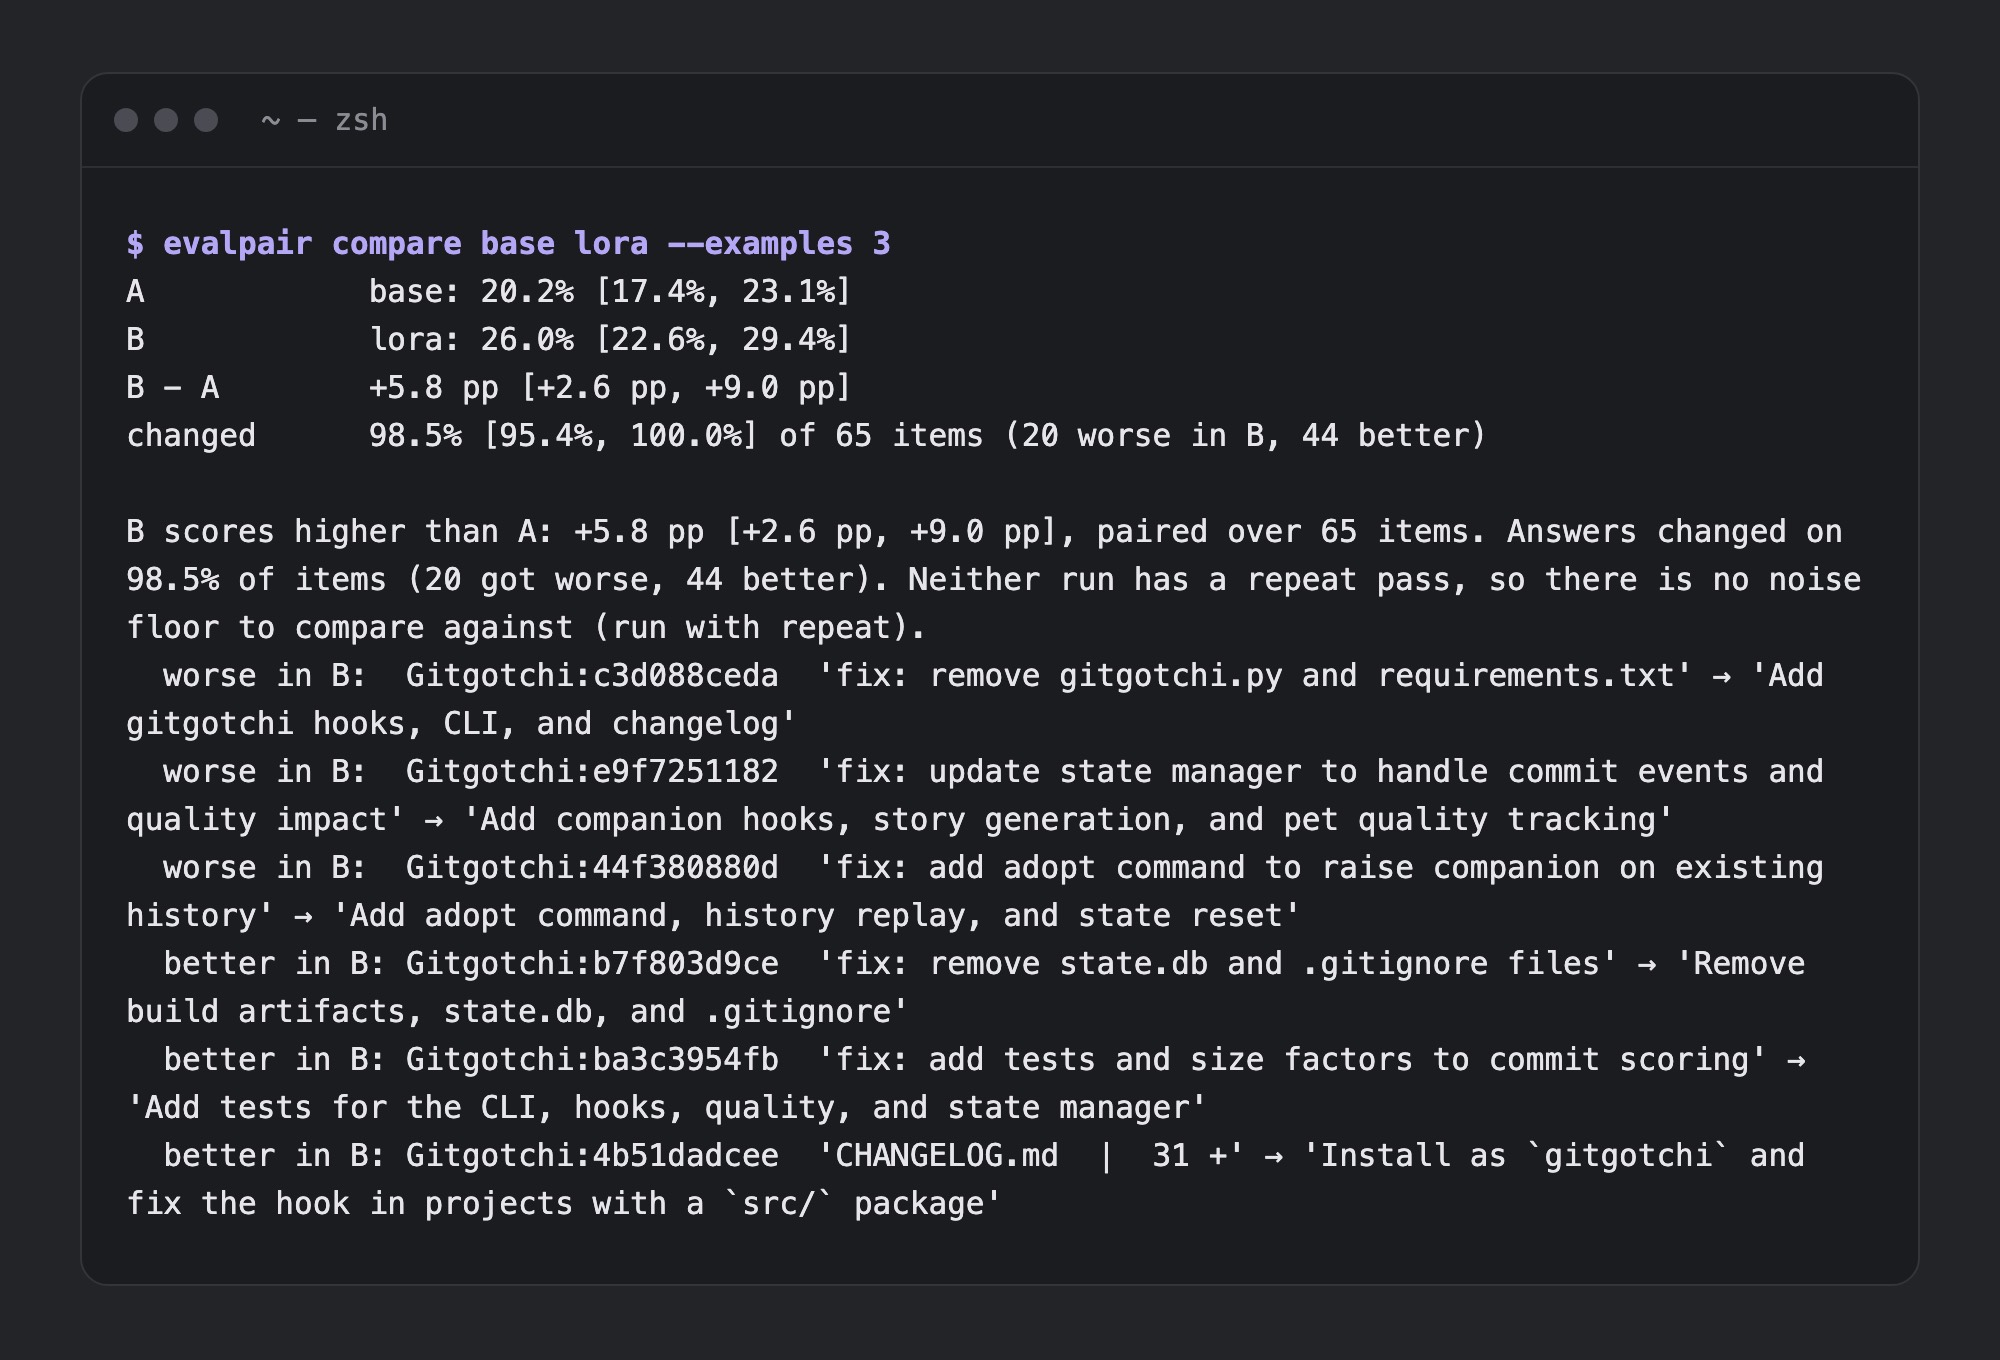
Runs an LLM eval suite against a local or hosted model, caches every call, and says whether two runs really differ: a paired interval on the difference, items that got worse and better, and a check against how much the same model changes when asked twice. A command-line tool and an MCP server, on PyPI and the MCP registry.
Every Boston City Council roll-call vote from 2008 to the latest meeting, searchable by topic, docket or councillor, and updated every morning from the City's pages. It checks each record against the clerk's written tally: of 1,530 that state one, 84 contradict it, and the site shows both.
Shows what a research paper is really standing on: the work it builds on, the work it argues with, and the assumptions it never defends. It reads all three straight from the paper's LaTeX, with no language model involved, and pins each one to the exact spot on the page. It covers 234 papers so far and publishes its own error rate: 80% precision on SciCite, 69% on ACL-ARC.
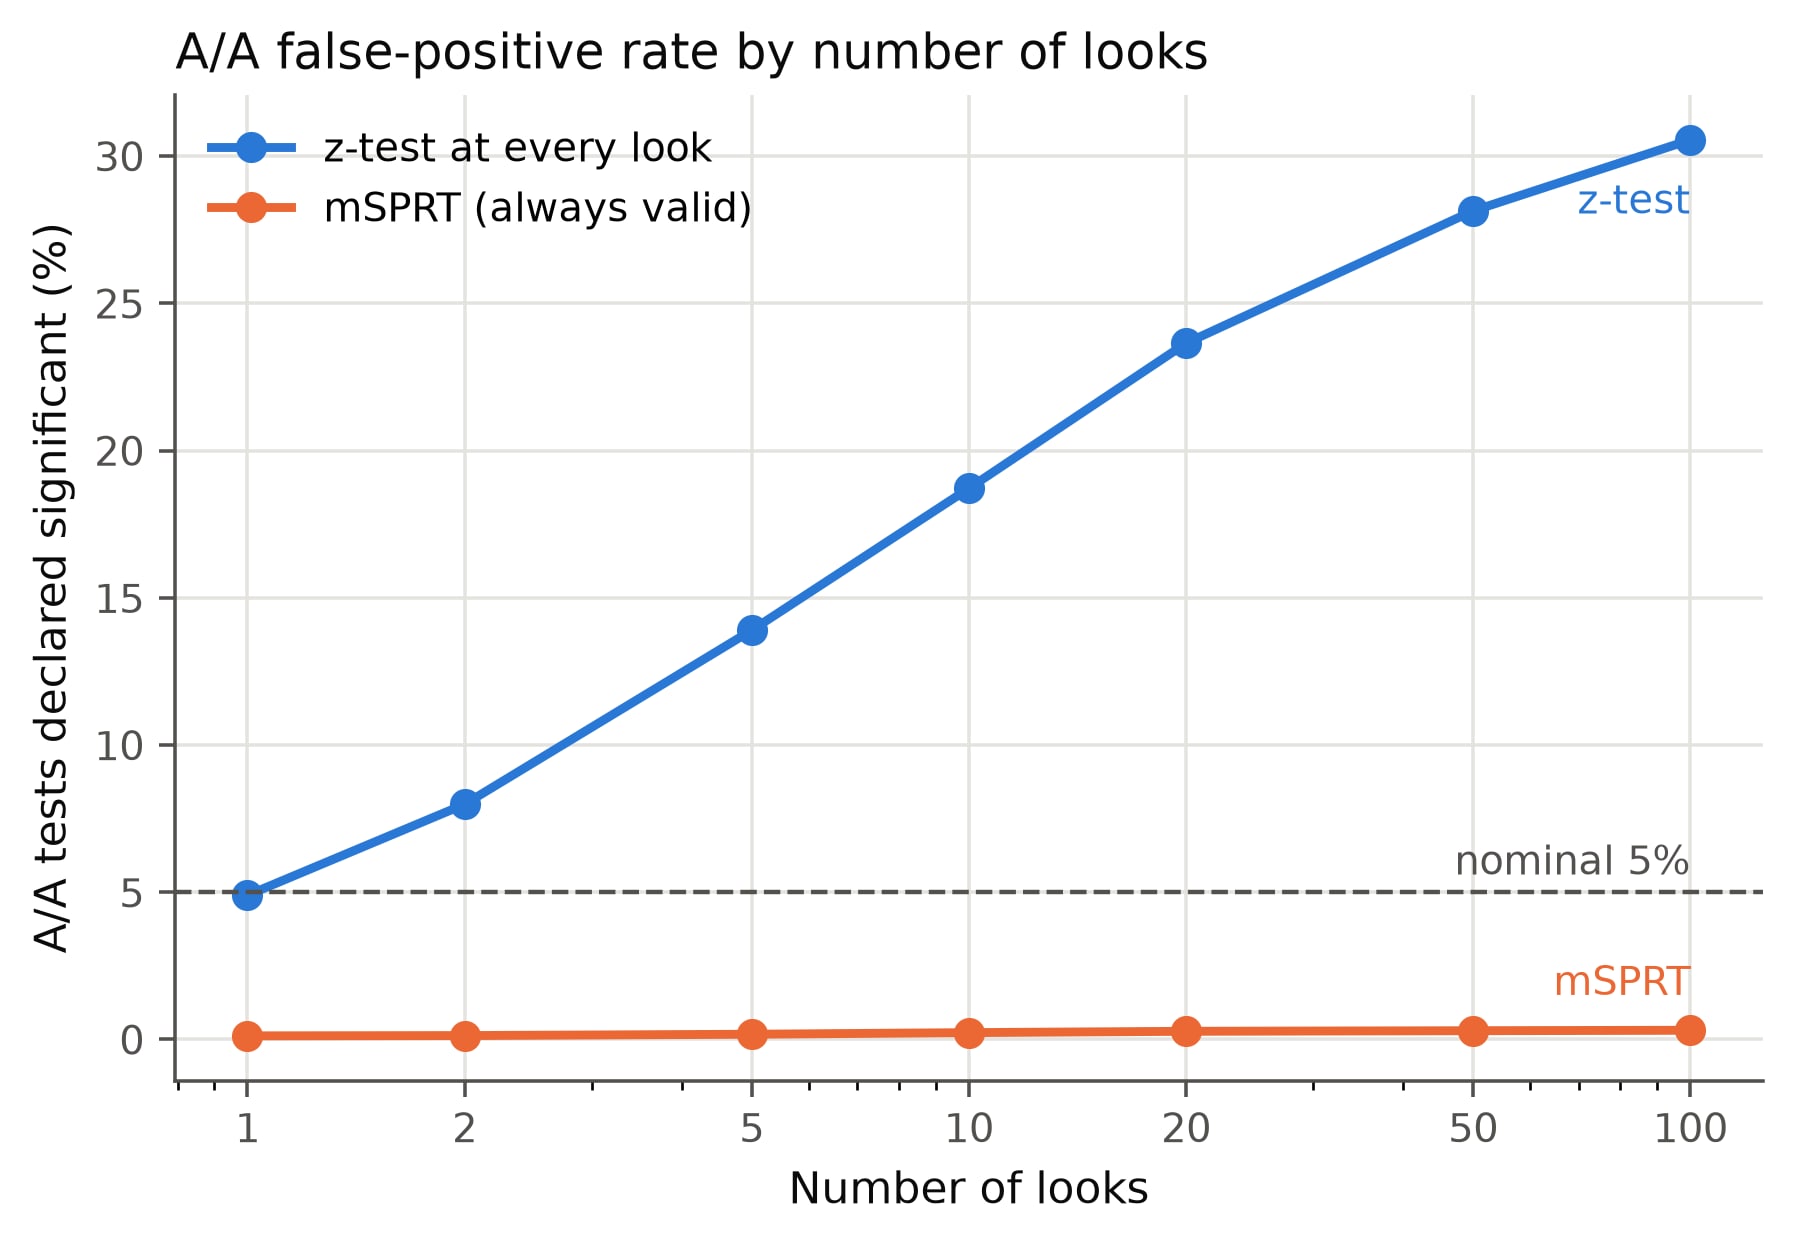
Re-analyses 22,743 real headline A/B tests from Upworthy and a 64,000-customer email test: how small real effects are, what checking early costs, how much winners shrink, and when variance reduction helps. The plan was locked before the confirmation data was opened, and every check replicated.
A benchmark for spotting when a RAG system's retrieval quietly gets worse, with no relevance labels. It injects five real-world failures (half-finished embedding upgrades, stale documents, chunking changes, query drift, config mistakes) at 10 to 90% severity and checks which label-free monitors catch them. My part: the retrieval pipeline, embedding cache, experiment runner and a re-embedding detector (in review). Northeastern capstone, in progress.
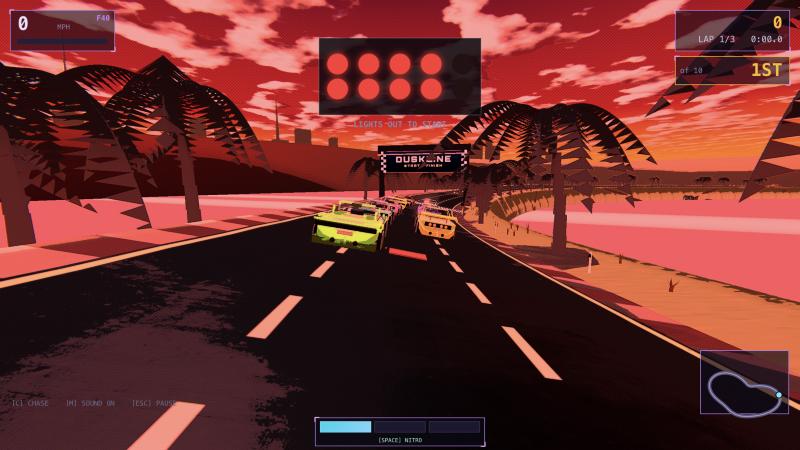
A racing game that runs in your browser, with nothing to install. Everything is made in code: the skies are shaders, the cars are modelled from cross-sections, and the engine, tyres, wind and music are synthesised live. 12 worlds, 14 cars and 4 modes, all built around drifting to charge your nitro. Works on phones, and offline.
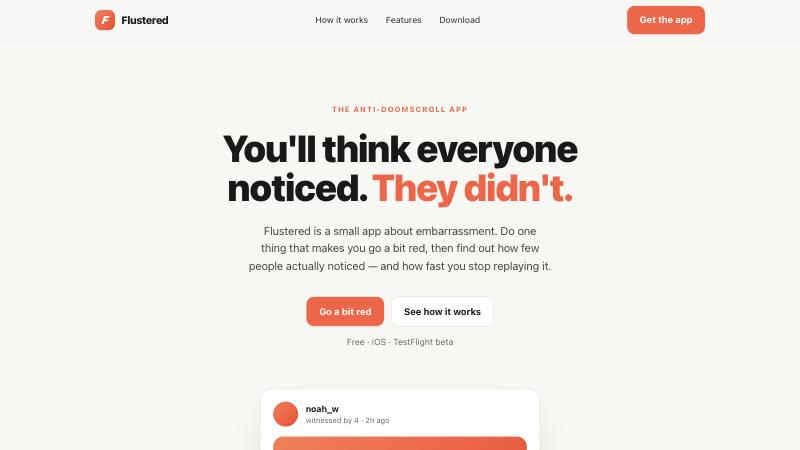
A small iOS app about embarrassment. Each day you do one thing that makes you go a bit red, share it privately, with a close circle or publicly, and find out how few people actually noticed. No infinite scroll and no like counts. Currently in TestFlight beta.
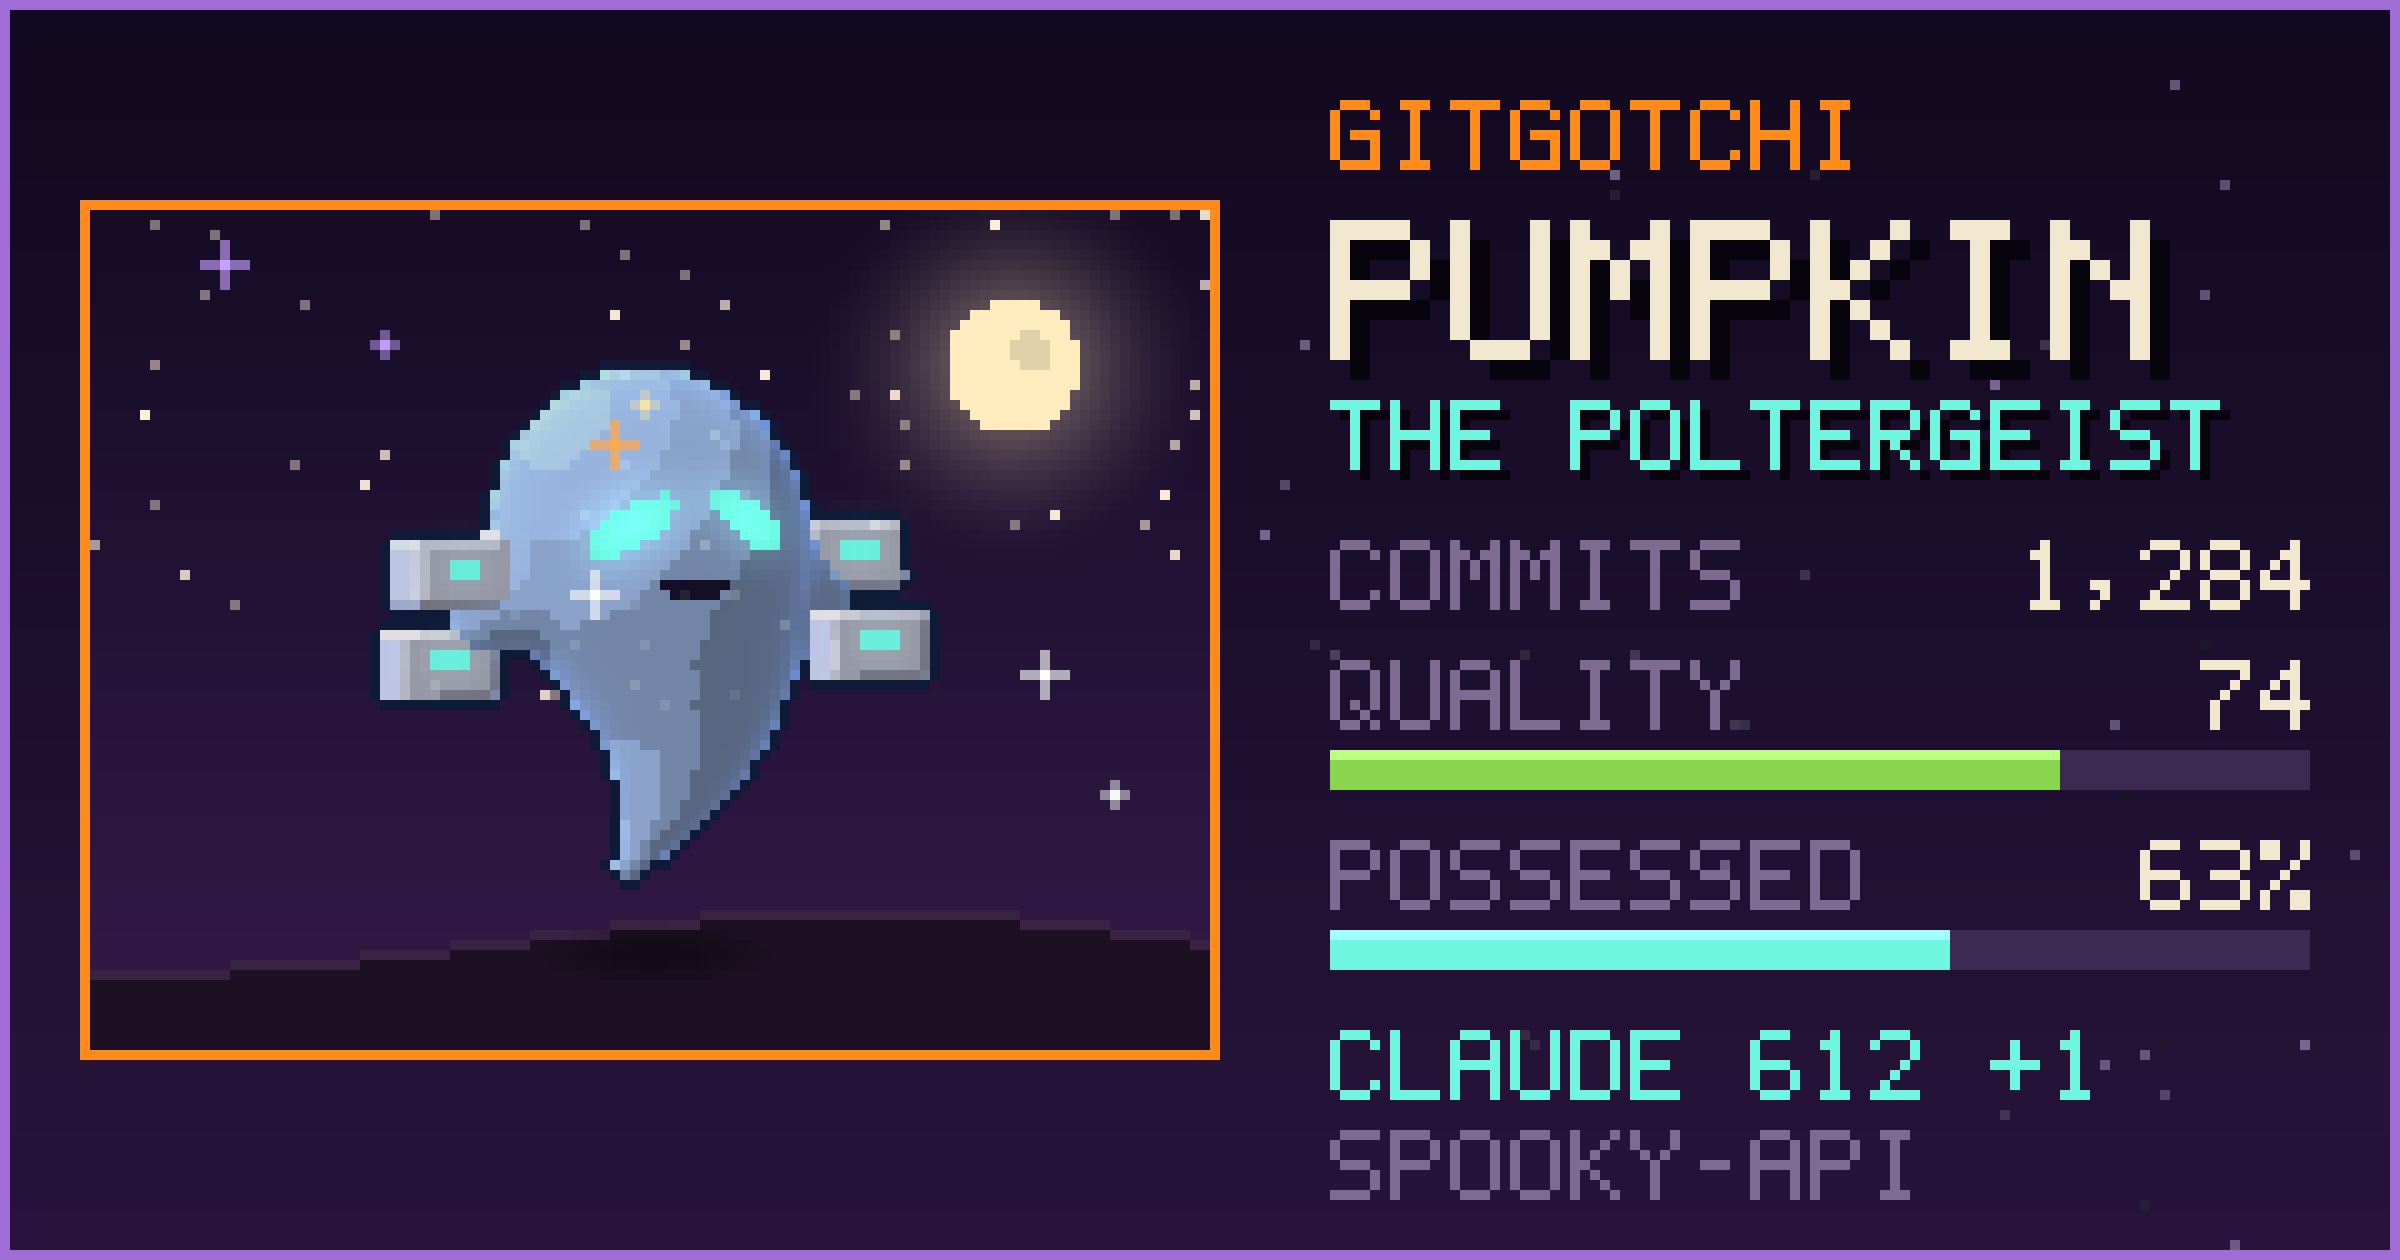
A companion that lives in your git repository and grows with how you commit. Commits written by AI agents slowly possess it, and every form is a 3D model drawn as pixel art in the terminal. On PyPI, with 200+ downloads.
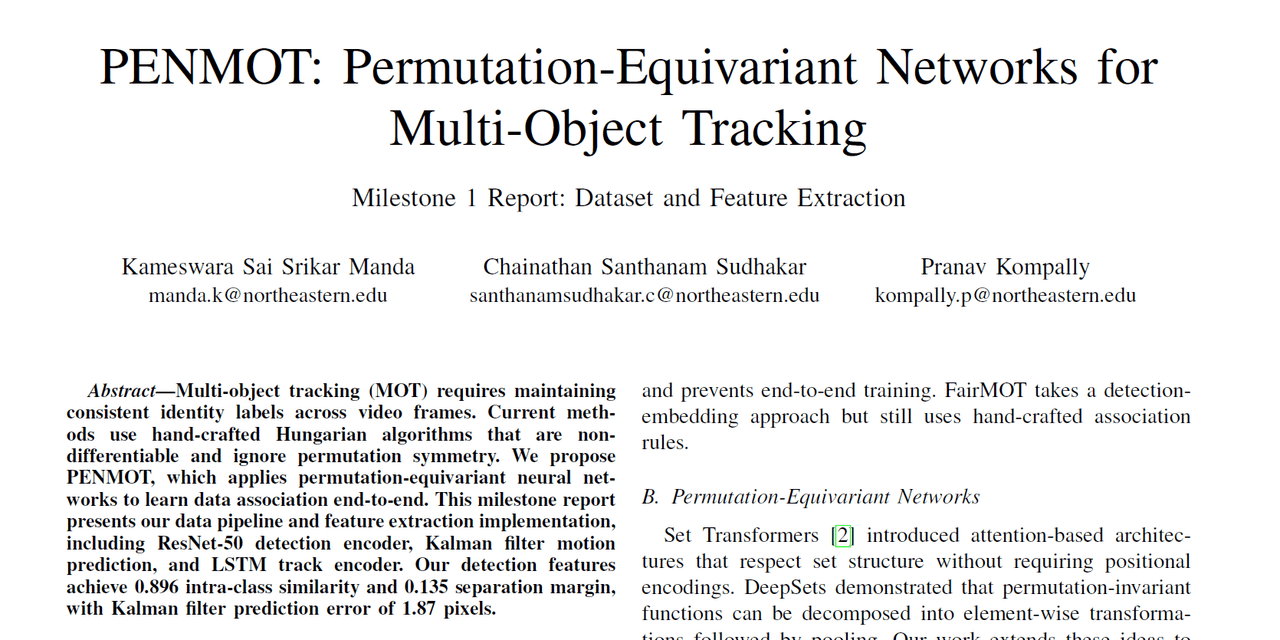
Tracks many objects through video at once by replacing the Hungarian matching step with a learned, permutation-equivariant Set Transformer and differentiable Sinkhorn matching, so the whole tracker trains end to end. On MOT17 the best hybrid setup reaches 82.6% MOTA, and adding motion cut ID switches by 78%; a plain IoU baseline still wins, which the report digs into. With Chainathan Santhanam Sudhakar and Pranav Kompally.
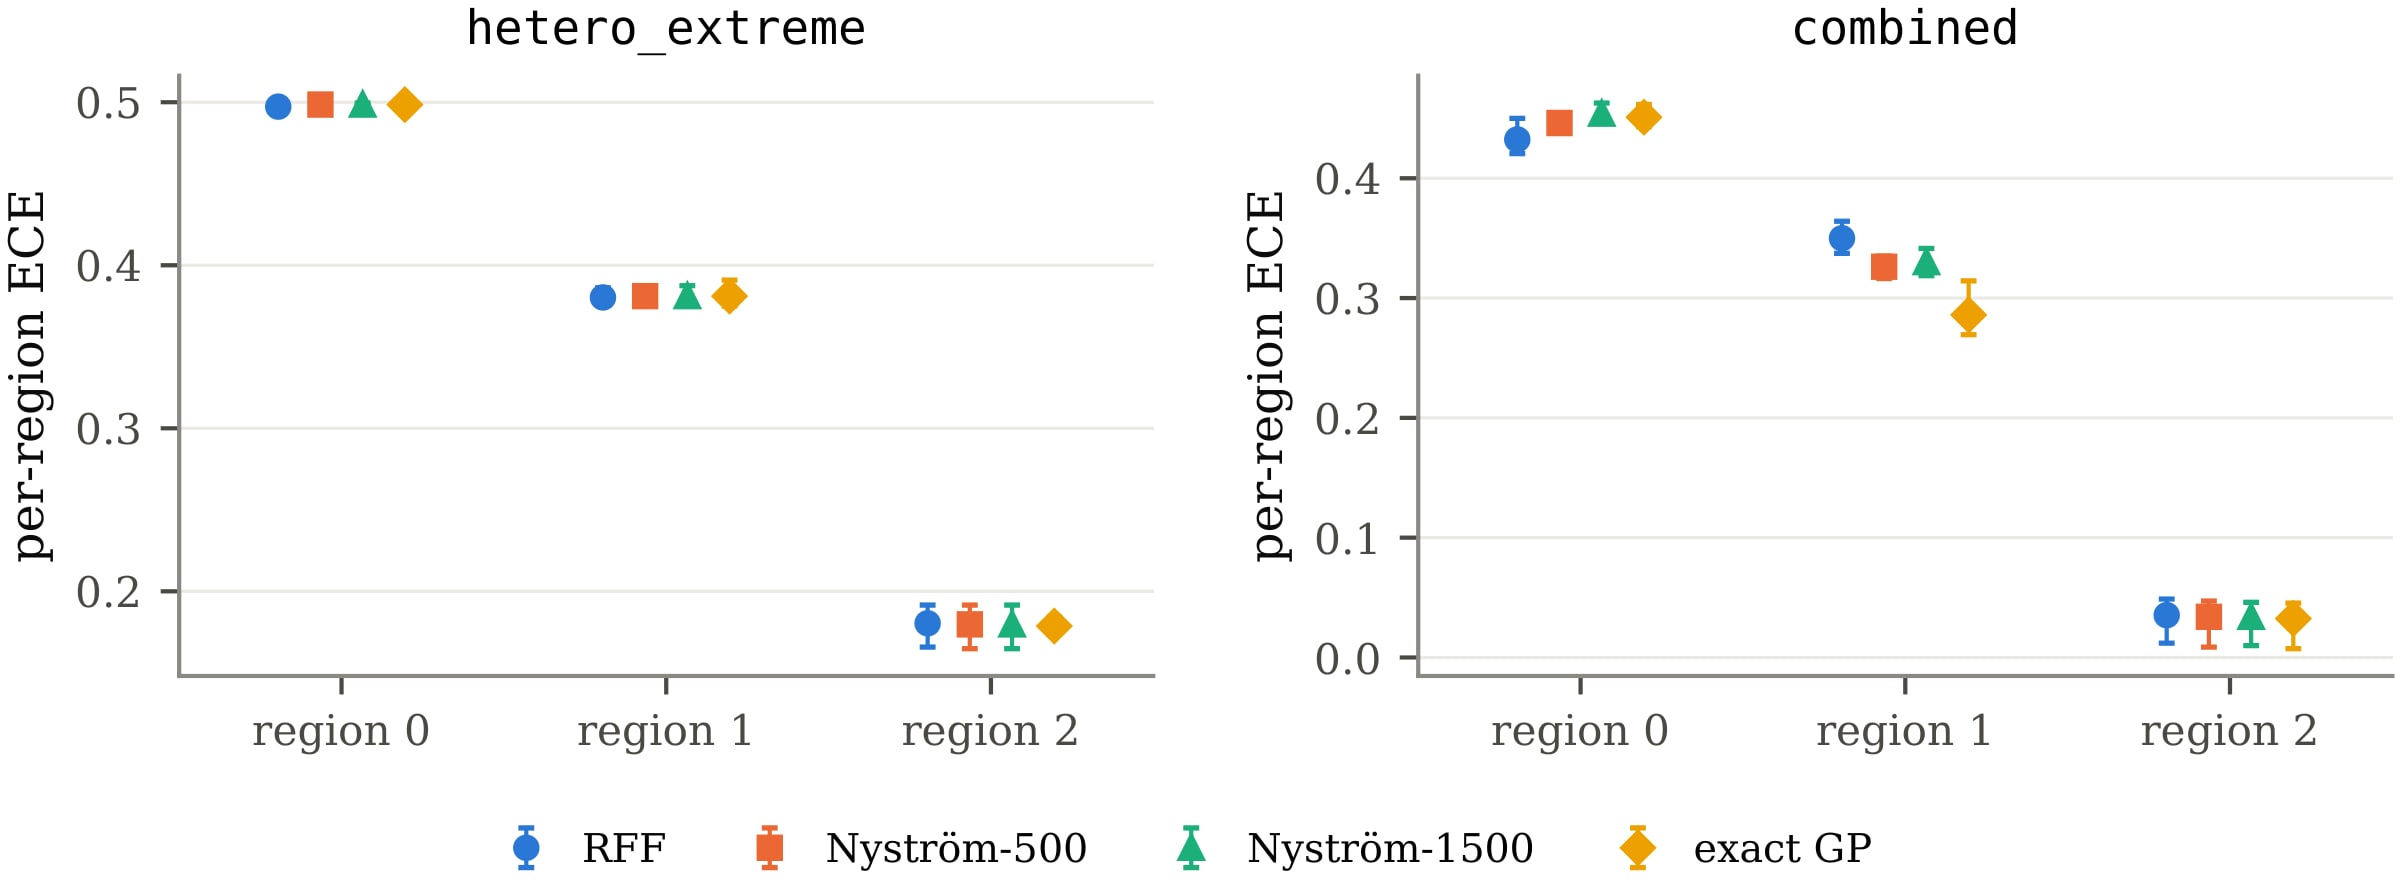
Region-aware Gaussian process approximation, and an audit of it. The first evaluation reported 41% better calibration; an audit nine months later traced that to a units bug. Corrected, routing the approximation by region doesn't help, but adapting the noise by region does, which is what the paper now argues. Original work with Alekhya Bulusu and Ming Ma.
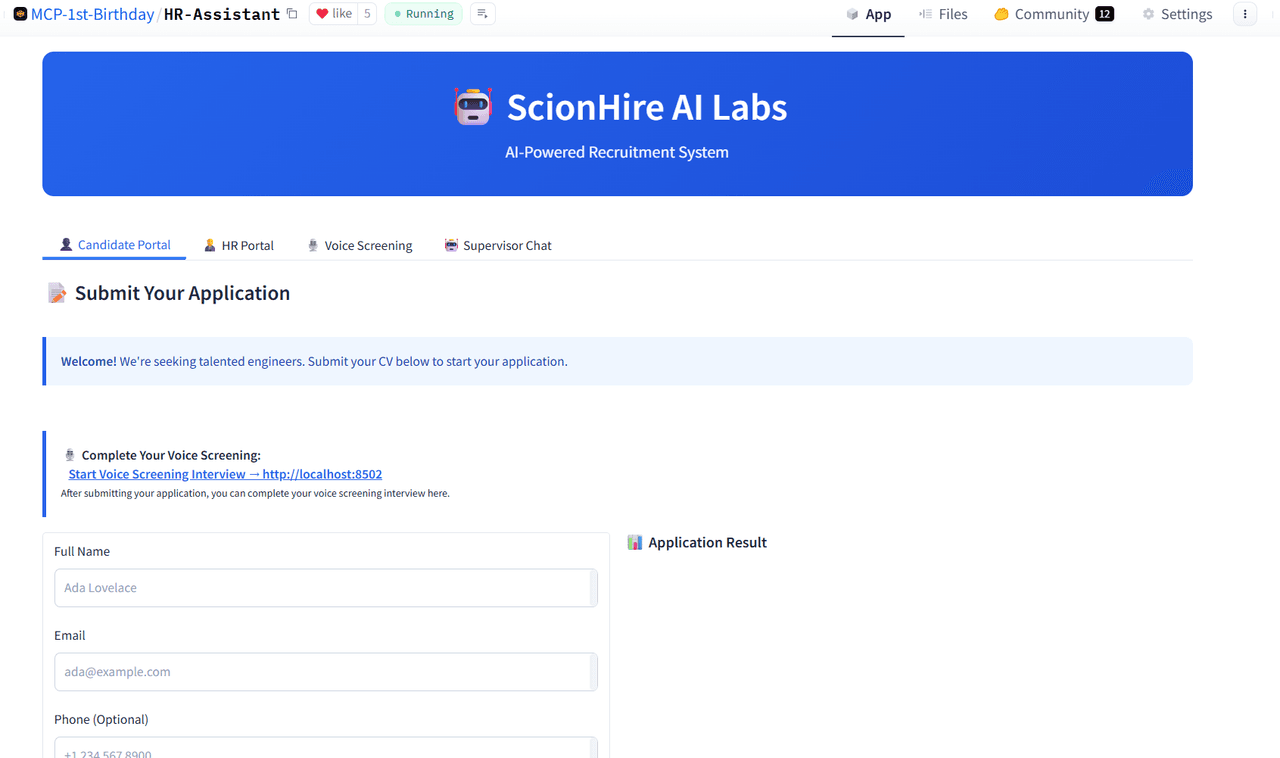
Takes the slow parts of hiring off a recruiter's plate: screening CVs, running voice interviews, sending emails and booking calendar slots. A supervisor agent hands each job to a specialist sub-agent, and Gmail and Google Calendar are connected through MCP servers. Built for the MCP 1st Birthday Hackathon.
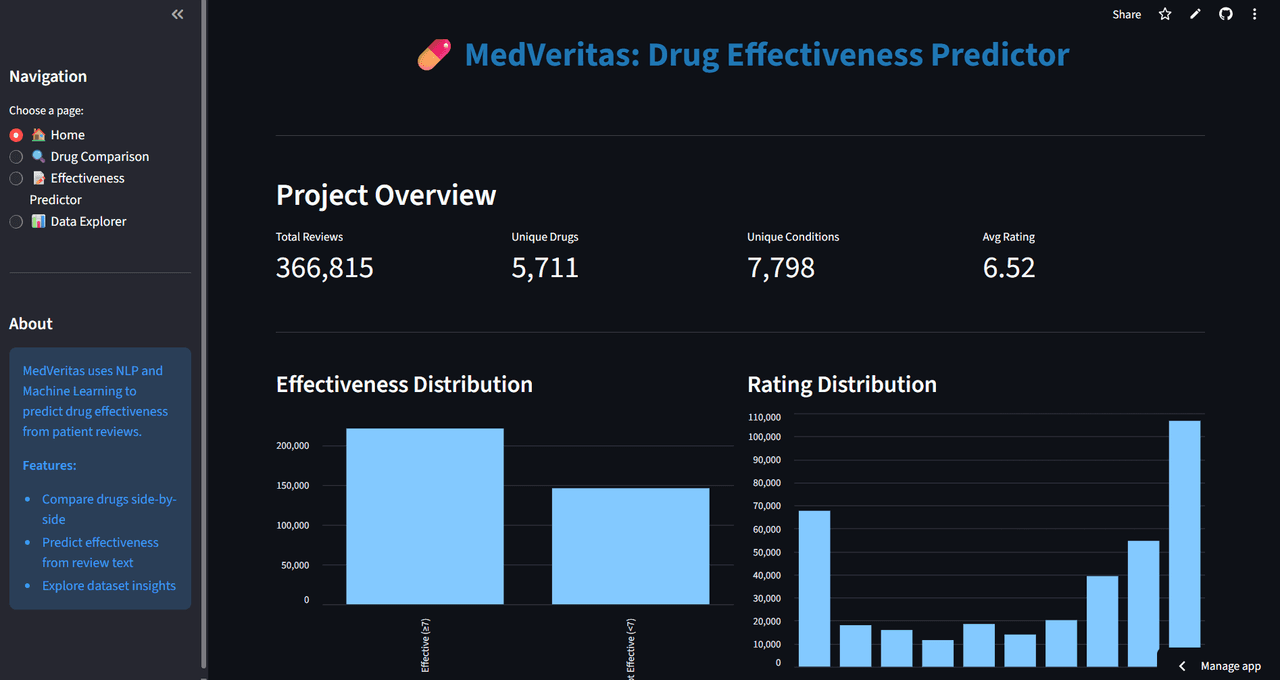
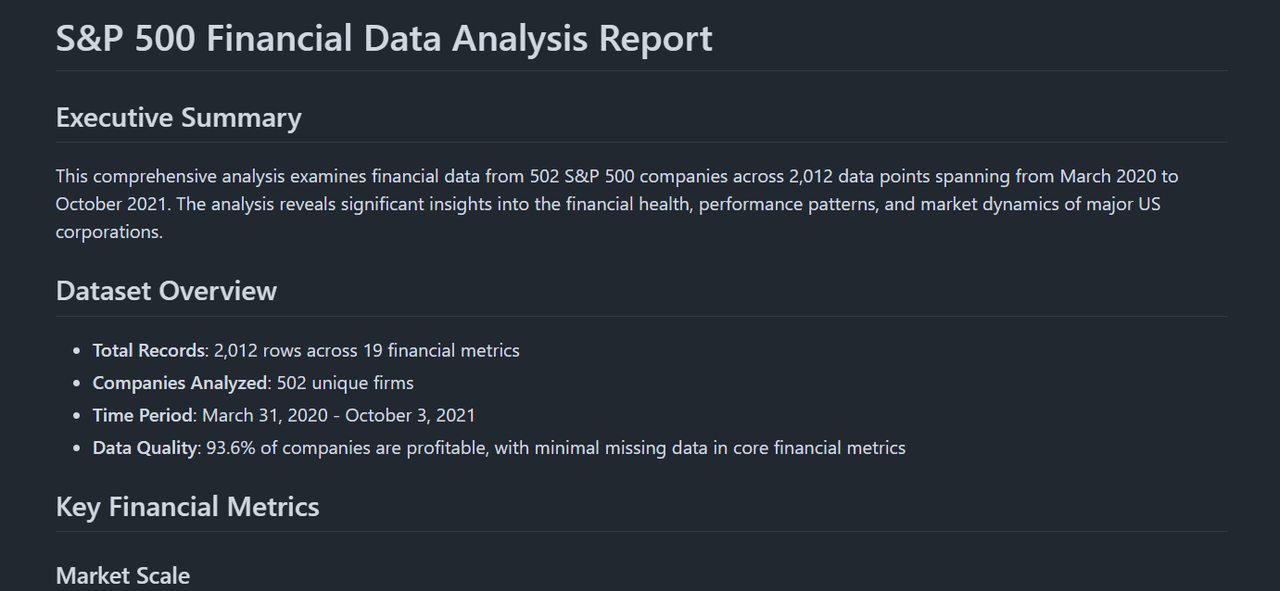
A Python toolkit for digging into the financials of S&P 500 companies: 502 companies and 2,012 data points, explored in Jupyter notebooks with charts and a written report.
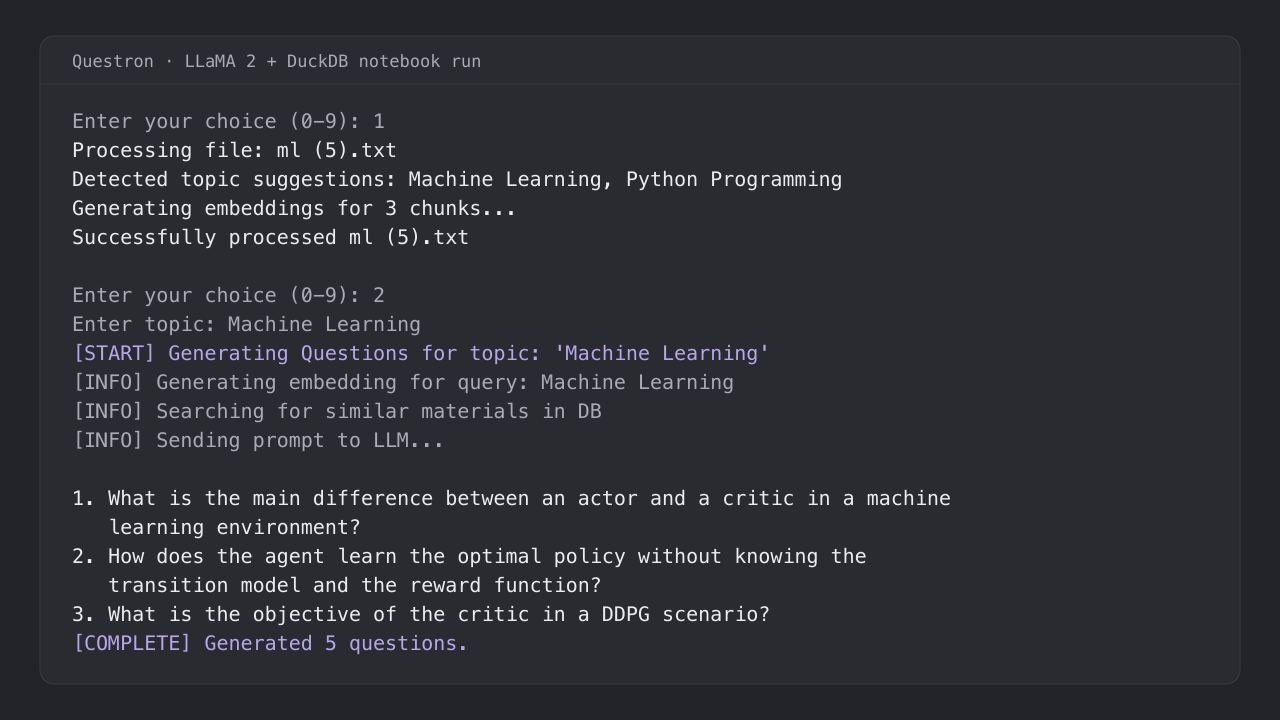
Generates quizzes and flashcards from course material. You upload a PDF or text file, it is chunked and embedded into DuckDB, and a local LLaMA 2 model retrieves the relevant chunks to write short-answer, multiple-choice and adaptive quizzes. It is a notebook prototype; the web front end was never finished.
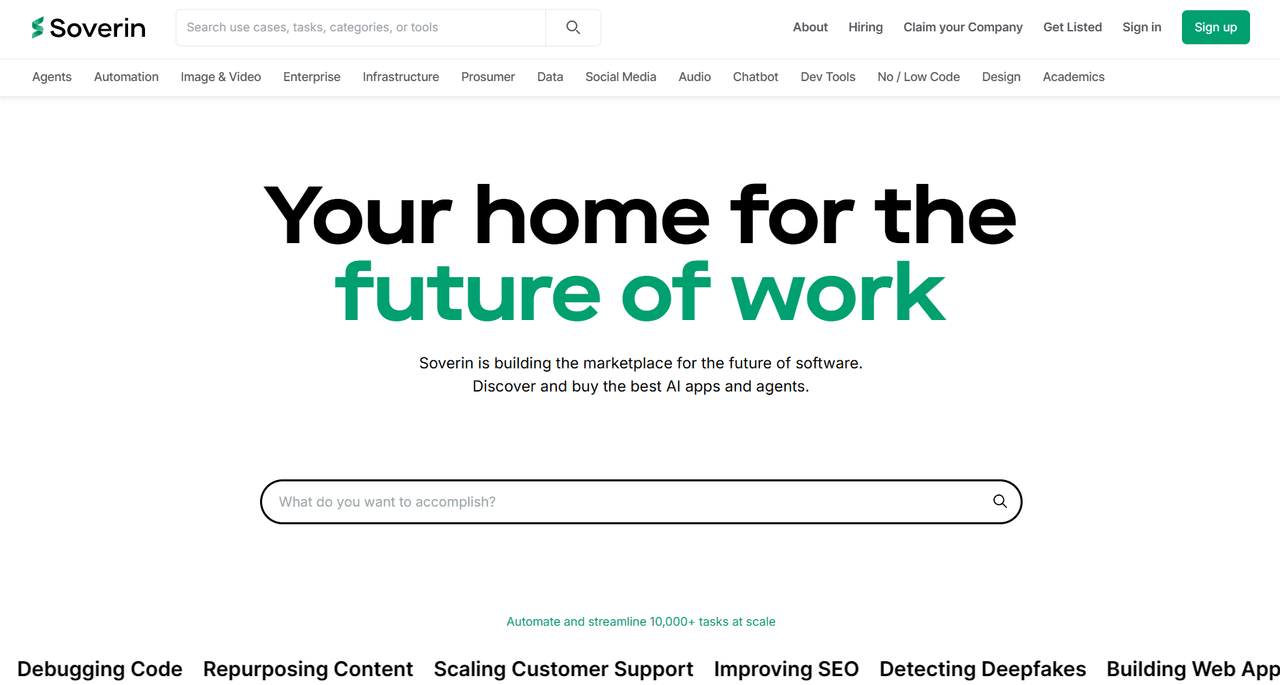
A marketplace for finding the right AI tool, built end to end with React, FastAPI, AWS and SQL. It grew to more than 10,000 people a month and a catalog of 1,900+ tools; reworking the query flow and indexing made search 30% faster and cut API latency by 40%.